Distilling Knowledge from Graph Convolutional Networks
Abstract
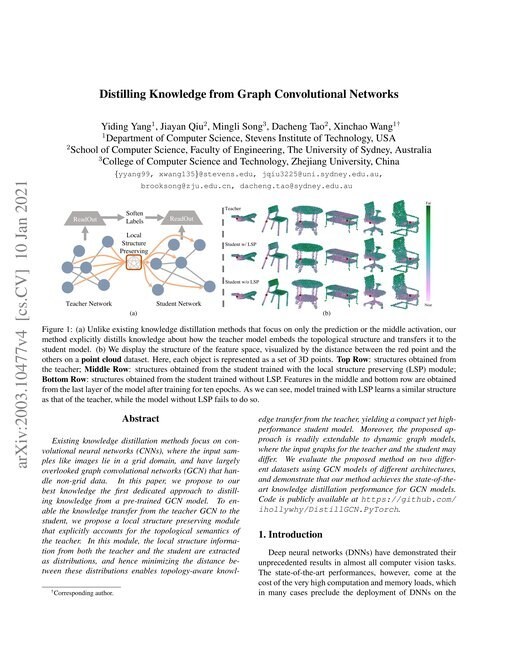
Existing knowledge distillation methods focus on convolutional neural networks (CNNs), where the input samples like images lie in a grid domain, and have largely overlooked graph convolutional networks (GCN) that handle non-grid data. In this paper, we propose to our best knowledge the first dedicated approach to distilling knowledge from a pre-trained GCN model. To enable the knowledge transfer from the teacher GCN to the student, we propose a local structure preserving module that explicitly accounts for the topological semantics of the teacher. In this module, the local structure information from both the teacher and the student are extracted as distributions, and hence minimizing the distance between these distributions enables topology-aware knowledge transfer from the teacher, yielding a compact yet high-performance student model. Moreover, the proposed approach is readily extendable to dynamic graph models, where the input graphs for the teacher and the student may differ. We evaluate the proposed method on two different datasets using GCN models of different architectures, and demonstrate that our method achieves the state-of-the-art knowledge distillation performance for GCN models. Code is publicly available at.
Benchmark Results
Tested on 1 dataset
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | F1 ↑ | Paper |
|---|---|---|---|
| 1 | GAMLP(JK) | 0.9982
±0.0001 | |
| 2 | GraphCON-GCN | 0.9960 | |
| 3 | GCNII | 0.9953
±0.0001 | |
| 21 | GCN | 0.9850 | |
| 50 | Teacher | 0.9760 | This paper |
| 74 | Student_LSP | 0.9610 | This paper |
| 78 | Student_Full | 0.9570 | This paper |
| 79 | Student_FitNet | 0.9560 | This paper |
| 80 | Student_AT | 0.9540 | This paper |
| 173 | MLP | 0.4620 |