SPAGAN: Shortest Path Graph Attention Network
Abstract
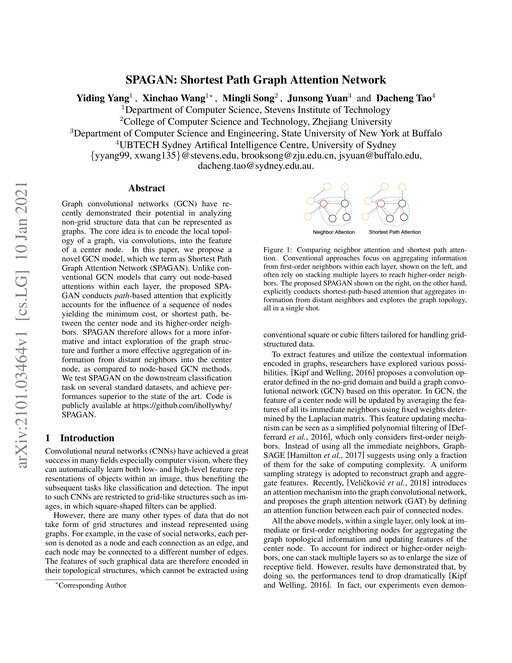
Graph convolutional networks (GCN) have recently demonstrated their potential in analyzing non-grid structure data that can be represented as graphs. The core idea is to encode the local topology of a graph, via convolutions, into the feature of a center node. In this paper, we propose a novel GCN model, which we term as Shortest Path Graph Attention Network (SPAGAN). Unlike conventional GCN models that carry out node-based attentions within each layer, the proposed SPAGAN conducts path-based attention that explicitly accounts for the influence of a sequence of nodes yielding the minimum cost, or shortest path, between the center node and its higher-order neighbors. SPAGAN therefore allows for a more informative and intact exploration of the graph structure and further a more effective aggregation of information from distant neighbors into the center node, as compared to node-based GCN methods. We test SPAGAN on the downstream classification task on several standard datasets, and achieve performances superior to the state of the art. Code is publicly available at.
Benchmark Results
Tested on 3 datasets 3 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 21 | GCN | 0.9004 best reported | best at pub: SplineCNN: Fast Geometric Deep Learning with Continuous B-Spline Kernels (2017) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 39 | SAGE | 0.8911
±0.0012 | |
| 44 | GAT | 0.8897
±0.0014 best reported | best at pub: Topology Adaptive Graph Convolutional Networks (2017) |
| 341 | SPAGAN | 0.8360
±0.0050 | This paper |
| 435 | DeepWalk | 0.8290 best reported | best at pub: Geometric deep learning on graphs and manifolds using mixture model CNNs (2016) best today: Graph Representation Learning: A Survey (2019) |
| 508 | MoNet | 0.8220
±0.0070 best reported | best at pub: Graph Attention Networks (ICLR 2017) best today: GRAND: Graph Neural Diffusion (ICML 2021) Difference within reported uncertainty; not counted as underperformance. |
| 590 | Chebyshev | 0.8120 | This paper |
| 591 | GAT^3 | 0.8120
±0.0060 | This paper |
| 724 | MLP | 0.7768 best reported | best at pub: Graph Attention Networks (ICLR 2017) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | CNA | 0.9575
±0.0058 | |
| 2 | IS-GIB | 0.9390
±0.0187 | |
| 3 | EERM | 0.9112
±0.0145 | |
| 35 | GAT | 0.8080
±0.0026 best reported | best at pub: Topology Adaptive Graph Convolutional Networks (2017) best today: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 44 | GCN | 0.8033
±0.0088 best reported | best at pub: Fast Graph Representation Learning with PyTorch Geometric (ICLR 2019) |
| 61 | GraphSAGE | 0.7923
±0.0053 | |
| 331 | SPAGAN | 0.7300
±0.0040 | This paper |
| 350 | MLP | 0.7289
±0.0010 best reported | best at pub: Fast Haar Transforms for Graph Neural Networks (2019) best today: Gumbel-MPNN: Graph Rewiring with Gumbel-Softmax (2025) |
| 617 | Chebyshev | 0.7010
±0.0080 best reported | best at pub: Graph Neural Networks With Convolutional ARMA Filters (2019) Difference within reported uncertainty; not counted as underperformance. |
| 661 | GAT^3 | 0.6880
±0.0070 | This paper |
| 692 | DeepWalk | 0.6785
±0.0079 best reported | best at pub: Topology Adaptive Graph Convolutional Networks (2017) best today: Decoupled Self-supervised Learning for Non-Homophilou Graphs (2022) |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | LGTL | 0.9518
±0.0011 | |
| 2 | MixHop (LO) | 0.9513
±0.0038 | |
| 3 | GraphSAGE (LO) | 0.9511
±0.0036 | |
| 18 | GCN | 0.9296
±0.0015 best reported | best at pub: Topology Adaptive Graph Convolutional Networks (2017) |
| 20 | GAT | 0.9233
±0.0018 best reported | best at pub: Topology Adaptive Graph Convolutional Networks (2017) |
| 116 | SAGE | 0.8881
±0.0015 | |
| 210 | MLP | 0.8690
±0.0074 best reported | best at pub: Graph Attention Networks (ICLR 2017) best today: On the Equivalence of Graph Convolution and Mixup (TMLR 2023) |
| 223 | DeepWalk | 0.8652
±0.0012 best reported | |
| 446 | MoNet | 0.8006
±0.0055 best reported | best at pub: Topology Adaptive Graph Convolutional Networks (2017) |
| 498 | SPAGAN | 0.7960
±0.0040 | This paper |
| 635 | GeniePath | 0.7850 | This paper |
| 639 | GAT^3 | 0.7850
±0.0040 | This paper |
| 807 | Chebyshev | 0.7440 | This paper |