Augmentation-Free Self-Supervised Learning on Graphs
Abstract
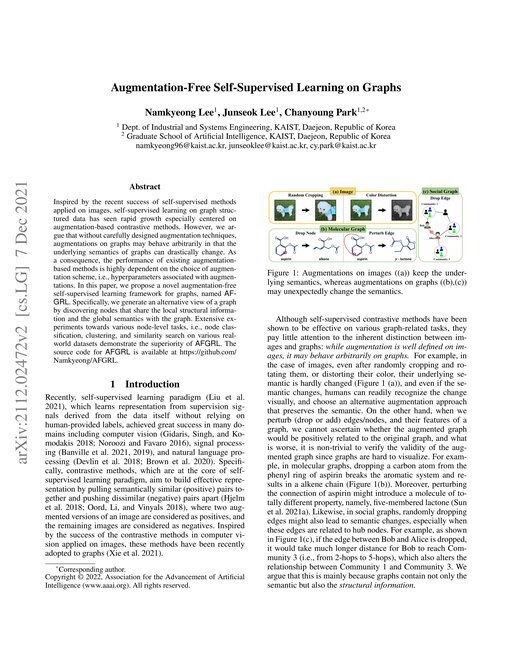
Inspired by the recent success of self-supervised methods applied on images, self-supervised learning on graph structured data has seen rapid growth especially centered on augmentation-based contrastive methods. However, we argue that without carefully designed augmentation techniques, augmentations on graphs may behave arbitrarily in that the underlying semantics of graphs can drastically change. As a consequence, the performance of existing augmentation-based methods is highly dependent on the choice of augmentation scheme, i.e., hyperparameters associated with augmentations. In this paper, we propose a novel augmentation-free self-supervised learning framework for graphs, named AFGRL. Specifically, we generate an alternative view of a graph by discovering nodes that share the local structural information and the global semantics with the graph. Extensive experiments towards various node-level tasks, i.e., node classification, clustering, and similarity search on various real-world datasets demonstrate the superiority of AFGRL. The source code for AFGRL is available at.
Benchmark Results
Tested on 4 datasets 5 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphTARIF | 0.9703
±0.0019 | |
| 2 | GAT | 0.9669
±0.0014 | |
| 3 | GAT+T | 0.9660
±0.0007 | |
| 7 | SAGE | 0.9643
±0.0027 | |
| 130 | AFGRL | 0.9361
±0.0020 best reported | best today: Wiener Graph Deconvolutional Network Improves Graph Self-Supervised Learning (AAAI 2022) Difference within reported uncertainty; not counted as underperformance. |
| 172 | BGRL | 0.9307
±0.0038 | prev best: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) Improvement within reported uncertainty; not highlighted. |
| 191 | GCA | 0.9320
±0.0060 best reported | best at pub: Calibrating and Improving Graph Contrastive Learning (TMLR 2021) best today: Decoupling Weighing and Selecting for Integrating Multiple Graph Pre-training Tasks (ICLR 2024) |
| 203 | GRACE | 0.9246
±0.0018 | prev best: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) best today: Learn Beneficial Noise as Graph Augmentation (ICML 2025) |
| 206 | MVGRL | 0.9310
±0.0040 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) best today: Decoupling Weighing and Selecting for Integrating Multiple Graph Pre-training Tasks (ICLR 2024) |
| 294 | Sup. GCN | 0.9242
±0.0022 | This paper |
| 390 | MLP | 0.9128
±0.0063 | |
| 408 | GMI | 0.9081
±0.0015 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) best today: Energy-Balanced Hyperspherical Graph Representation Learning via Structural Binding and Entropic Dispersion (2025) Difference within reported uncertainty; not counted as underperformance. |
| 445 | DW + feats. | 0.9005
±0.0008 | This paper |
| 457 | Node2Vec | 0.8970
±0.0010 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) best today: Multiplex Graph Contrastive Learning with Soft Negatives (2024) Difference within reported uncertainty; not counted as underperformance. |
| 538 | Raw feats. | 0.7853 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphTARIF | 0.9461
±0.0017 | |
| 2 | GCN | 0.9412
±0.0008 | |
| 3 | GAT | 0.9398
±0.0022 | |
| 8 | SAGE | 0.9351
±0.0006 | |
| 79 | BGRL | 0.8969
±0.0037 | prev best: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) best today: Adaptive Negative Scheduling for Graph Contrastive Learning (2026) Improvement within reported uncertainty; not highlighted. |
| 112 | AFGRL | 0.8988
±0.0033 | This paper |
| 139 | GRACE | 0.8953
±0.0035 best reported | best at pub: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) best today: Adaptive Negative Scheduling for Graph Contrastive Learning (2026) |
| 160 | GCA | 0.8894
±0.0015 best reported | best at pub: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) best today: Adaptive Negative Scheduling for Graph Contrastive Learning (2026) |
| 179 | MVGRL | 0.8861
±0.0064 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) |
| 210 | DGI | 0.8798
±0.0081 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) best today: Bootstrap Latents of Nodes and Neighbors for Graph Self-Supervised Learning (2024) |
| 270 | Sup. GCN | 0.8651
±0.0054 | This paper |
| 278 | DeepWalk | 0.8628
±0.0007 best reported | best at pub: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) |
| 280 | DW + feats. | 0.8628
±0.0007 | This paper |
| 320 | MLP | 0.8463 | |
| 330 | Node2Vec | 0.8440
±0.0010 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) best today: Multiplex Graph Contrastive Learning with Soft Negatives (2024) Difference within reported uncertainty; not counted as underperformance. |
| 342 | GMI | 0.8422
±0.0052 best reported | best at pub: Graph Contrastive Learning with Adaptive Augmentation (WWW 2020) best today: Localized Graph Contrastive Learning (2022) |
| 458 | Raw feats. | 0.7381 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GrokFormer | 0.9831
±0.0018 | |
| 2 | PolyFormer | 0.9808
±0.0027 | |
| 3 | SGFormer | 0.9796
±0.0081 | |
| 9 | GCN | 0.9774
±0.0035 | |
| 58 | MLP | 0.9597
±0.0007 | |
| 69 | BGRL | 0.9580
±0.0040 best reported | best at pub: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) best today: Unifying Graph Contrastive Learning with Flexible Contextual Scopes (2022) Difference within reported uncertainty; not counted as underperformance. |
| 78 | AFGRL | 0.9574
±0.0010 best reported | best today: Wiener Graph Deconvolutional Network Improves Graph Self-Supervised Learning (AAAI 2022) Difference within reported uncertainty; not counted as underperformance. |
| 93 | Sup. GCN | 0.9565
±0.0016 | This paper |
| 164 | DW + feats. | 0.9490
±0.0009 | This paper |
| 213 | Raw feats. | 0.9358 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GCN | 0.9302
±0.0011 | |
| 2 | RSE + RGCN (70b) | 0.8852
±0.0019 | |
| 3 | LEMP+T | 0.8825 | |
| 9 | SAGE | 0.8771 | |
| 94 | GRACE | 0.8014
±0.0048 best reported | best at pub: Large-Scale Representation Learning on Graphs via Bootstrapping (ICLR 2021) best today: Adaptive Negative Scheduling for Graph Contrastive Learning (2026) |
| 100 | BGRL | 0.8000
±0.0010 best reported | best at pub: Large-Scale Representation Learning on Graphs via Bootstrapping (ICLR 2021) best today: PyG-SSL: A Graph Self-Supervised Learning Toolkit (2024) |
| 143 | AFGRL | 0.7890
±0.0060 best reported | best today: PyG-SSL: A Graph Self-Supervised Learning Toolkit (2024) |
| 151 | DGI | 0.7865
±0.0690 best reported | best at pub: Graph Barlow Twins: A self-supervised representation learning framework for graphs (2021) best today: Quantizing Text-attributed Graphs for Semantic-Structural Integration (KDD 2025) Difference within reported uncertainty; not counted as underperformance. |
| 162 | GCA | 0.7840
±0.0013 best reported | best at pub: Graph Barlow Twins: A self-supervised representation learning framework for graphs (2021) best today: Augmentation-Free Graph Contrastive Learning with Performance Guarantee (2022) Difference within reported uncertainty; not counted as underperformance. |
| 190 | MVGRL | 0.7757
±0.0046 best reported | best at pub: Graph Barlow Twins: A self-supervised representation learning framework for graphs (2021) best today: Negative-Free Self-Supervised Gaussian Embedding of Graphs (2024) Difference within reported uncertainty; not counted as underperformance. |
| 198 | DeepWalk | 0.7721 best reported | best at pub: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) |
| 199 | DW + feats. | 0.7721
±0.0003 | This paper |
| 204 | Sup. GCN | 0.7719
±0.0012 | This paper |
| 234 | GMI | 0.7490
±0.0010 best reported | best at pub: Barlow Graph Auto-Encoder for Unsupervised Network Embedding (2021) best today: Learning Graph Augmentations to Learn Graph Representations (2022) Difference within reported uncertainty; not counted as underperformance. |
| 237 | MLP | 0.7469
±0.0085 | |
| 254 | Raw feats. | 0.7198 | This paper |
| 258 | Node2Vec | 0.7180
±0.0010 best reported | best today: Learning Graph Augmentations to Learn Graph Representations (2022) Difference within reported uncertainty; not counted as underperformance. |