GRPE: Relative Positional Encoding for Graph Transformer
Abstract
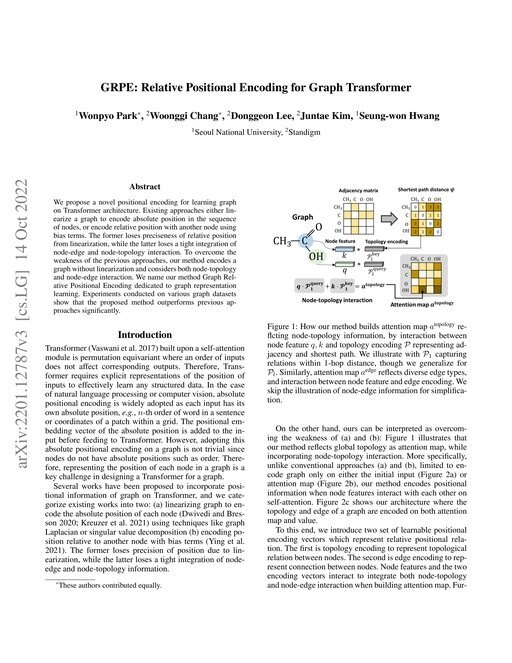
We propose a novel positional encoding for learning graph on Transformer architecture. Existing approaches either linearize a graph to encode absolute position in the sequence of nodes, or encode relative position with another node using bias terms. The former loses preciseness of relative position from linearization, while the latter loses a tight integration of node-edge and node-topology interaction. To overcome the weakness of the previous approaches, our method encodes a graph without linearization and considers both node-topology and node-edge interaction. We name our method Graph Relative Positional Encoding dedicated to graph representation learning. Experiments conducted on various graph datasets show that the proposed method outperforms previous approaches significantly.
Benchmark Results
Tested on 4 datasets
Tables show presented results in global context (best 3 papers + GCN + MLP).
OGB
| # | Model | ROC-AUC ↑ | Paper |
|---|---|---|---|
| 1 | Multi-RF Fusion with Multi-GNN Blending | 0.8476
±0.0002 | |
| 2 | HyperFusion | 0.8475
±0.0003 | |
| 3 | PAS+FPs | 0.8420
±0.0015 | |
| 5 | GRPE-Standard | 0.8139
±0.0049 | This paper |
| 9 | GatedGCN | 0.8090
±0.0160 | |
| 11 | EGT-Large | 0.8060
±0.0065 | This paper |
| 15 | Graphormer-FLAG | 0.8051
±0.0053 | This paper |
| 37 | DGN | 0.7970
±0.0097 | This paper |
| 45 | DeeperGCN-FLAG | 0.7942
±0.0120 | This paper |
| 47 | PHC-GNN | 0.7934
±0.0116 | This paper |
| 62 | PNA | 0.7905
±0.0132 | This paper |
| 68 | GCN-GraphNorm | 0.7883
±0.0100 | This paper |
| 109 | GIN | 0.7780
±0.0182 | Improvement within reported uncertainty; not highlighted. |
| 160 | GraphSAGE | 0.7690
±0.0136 |
| # | Model | AP ↑ | Paper |
|---|---|---|---|
| 1 | GRPE-Large | 0.3150
±0.0010 | This paper |
| 2 | Graphormer | 0.3140 | |
| 3 | Graphormer-FLAG | 0.3139
±0.0032 | This paper |
| 6 | GRPE-Standard | 0.3077
±0.0007 | This paper |
| 12 | GINE | 0.2979
±0.0030 | This paper |
| 16 | EGT-Large | 0.2961
±0.0024 | This paper |
| 19 | PHC-GNN | 0.2947
±0.0026 | This paper |
| 31 | GIN | 0.2902
±0.0017 | |
| 33 | DGN | 0.2885
±0.0030 | This paper |
| 36 | DeeperGCN+FLAG | 0.2842
±0.0043 | This paper |
| 56 | GCN | 0.2690
±0.0020 |
| # | Model | MAE ↓ | Paper |
|---|---|---|---|
| 1 | DeMol | 0.0603 | |
| 2 | TGT-At | 0.0671 | |
| 3 | TGT-At (+RDKit) | 0.0683 | |
| 31 | Graphormer | 0.0864 best reported | best today: Enhancing Molecular Property Predictions by Learning from Bond Modelling and Interactions (ICLR 2026) |
| 34 | EGT-Large | 0.0869 best reported | best today: IJCAI--23 Formatting Instructions (IJCAI 2023) |
| 39 | GRPE-Standard | 0.0890 best reported | best today: IJCAI--23 Formatting Instructions (IJCAI 2023) |
| 58 | GIN-VN | 0.1083 best reported | best today: Enhancing Molecular Property Predictions by Learning from Bond Modelling and Interactions (ICLR 2026) |
| 60 | GCN-VN | 0.1152 | This paper |
| 65 | GCN | 0.1195 best reported | best today: Enhancing Graph Neural Networks with Quantum Computed Encodings (2023) |
| 64 | GIN | 0.1195 best reported | best today: Enhancing Molecular Property Predictions by Learning from Bond Modelling and Interactions (ICLR 2026) |
GNNBenchmark
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GRPE-Small | 0.8159
±0.0019 | This paper |
| 2 | TANGO-GPS | 0.8011
±0.0014 | |
| 3 | GRIT | 0.8003
±0.0028 | |
| 6 | EGT | 0.7923
±0.0035 | This paper |
| 50 | SAN | 0.7669
±0.0065 | This paper |
| 54 | GatedGCN | 0.7608
±0.0020 | prev best: Formatting Instructions for ICLR 2021 Conference Submissions (2020) |
| 60 | Graphormer (slim) | 0.7466
±0.0024 | This paper |
| 63 | GT | 0.7317
±0.0062 | This paper |
| 67 | GAT | 0.7059
±0.0045 | This paper |
| 70 | GCN | 0.6903
±0.0137 best reported | best at pub: How Expressive are Transformers in Spectral Domain for Graphs? (TMLR 2022) best today: Recurrent Distance Filtering for Graph Representation Learning (ICML 2023) Difference within reported uncertainty; not counted as underperformance. |
| 79 | GIN | 0.6472
±0.0155 | This paper |
| 80 | GraphSAGE | 0.6388
±0.0011 | |
| 114 | MLP | 0.2097
±0.0000 |