1-WL Expressiveness Is (Almost) All You Need
Abstract
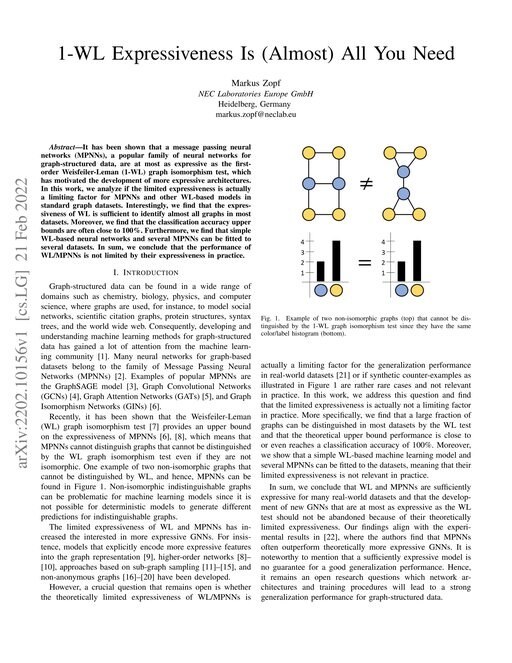
It has been shown that a message passing neural networks (MPNNs), a popular family of neural networks for graph-structured data, are at most as expressive as the first-order Weisfeiler-Leman (1-WL) graph isomorphism test, which has motivated the development of more expressive architectures. In this work, we analyze if the limited expressiveness is actually a limiting factor for MPNNs and other WL-based models in standard graph datasets. Interestingly, we find that the expressiveness of WL is sufficient to identify almost all graphs in most datasets. Moreover, we find that the classification accuracy upper bounds are often close to 100\
Benchmark Results
Tested on 2 datasets 3 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
TU Dortmund
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9954 | This paper |
| 2 | GIN | 0.9934 | prev best: Provably Powerful Graph Networks (NeurIPS 2019) |
| 3 | GCN | 0.9727 | prev best: Hierarchical Graph Capsule Network (AAAI 2020) |
| 4 | GAT | 0.9623 | prev best: Weisfeiler and Leman Go Infinite: Spectral and Combinatorial Pre-Colorings (TMLR 2022) |
| 131 | GraphSAGE | 0.8200
±0.0100 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9792 | This paper |
| 2 | MSH-GNN | 0.9640
±0.0070 | |
| 3 | CoCN | 0.8722
±0.0013 | |
| 23 | GCN | 0.8260
±0.0220 best reported | best at pub: Fast Graph Representation Learning with PyTorch Geometric (ICLR 2019) best today: Scalable Expressiveness through Preprocessed Graph Perturbations (2024) |
| 30 | GIN | 0.8220
±0.0210 best reported | best at pub: On the Equivalence between Graph Isomorphism Testing and Function Approximation with GNNs (NeurIPS 2019) best today: Scalable Expressiveness through Preprocessed Graph Perturbations (2024) |
| 136 | GraphSAGE | 0.7970
±0.0170 | |
| 151 | MLP | 0.7920
±0.0240 | |
| 155 | GAT | 0.7908
±0.0136 best reported | best at pub: Improving Subgraph Recognition with Variational Graph Information Bottleneck (2021) best today: Graph Structure Refinement with Energy-based Contrastive Learning (AAAI 2024) |