A*Net: A Scalable Path-based Reasoning Approach for Knowledge Graphs
Abstract
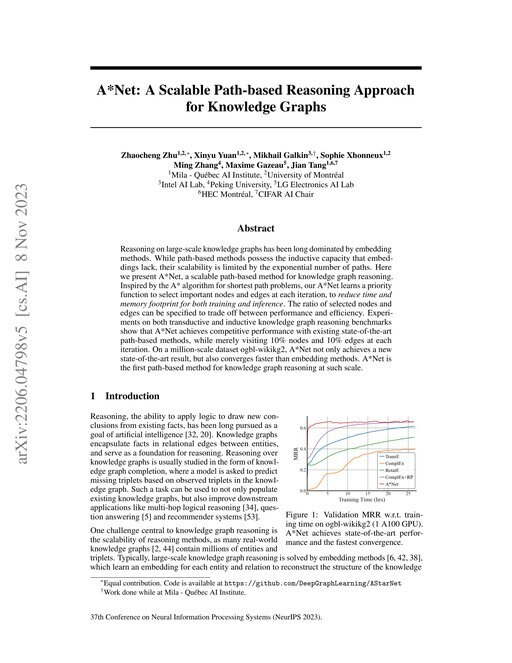
Reasoning on large-scale knowledge graphs has been long dominated by embedding methods. While path-based methods possess the inductive capacity that embeddings lack, their scalability is limited by the exponential number of paths. Here we present A*Net, a scalable path-based method for knowledge graph reasoning. Inspired by the A* algorithm for shortest path problems, our A*Net learns a priority function to select important nodes and edges at each iteration, to reduce time and memory footprint for both training and inference. The ratio of selected nodes and edges can be specified to trade off between performance and efficiency. Experiments on both transductive and inductive knowledge graph reasoning benchmarks show that A*Net achieves competitive performance with existing state-of-the-art path-based methods, while merely visiting 10\
Benchmark Results
Tested on 3 datasets 3 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
OGB
| # | Model | MRR ↑ | Paper |
|---|---|---|---|
| 1 | InterHT + DigPiece | 0.7293
±0.0018 | |
| 2 | StarGraph + TripleRE' | 0.7290 | |
| 3 | TripleRE + StarGraph | 0.7201
±0.0011 | |
| 6 | A*Net | 0.6767 | This paper |
| 12 | ComplEx+RP | 0.6392 | This paper |
| 20 | PairRE | 0.5805 best reported | |
| 29 | TransE | 0.4536
±0.0030 best reported | best at pub: PairRE: Knowledge Graph Embeddings via Paired Relation Vectors (2020) |
| 30 | RotatE | 0.4332 | This paper |
| 36 | ComplEx | 0.4028
±0.0030 best reported | best at pub: PairRE: Knowledge Graph Embeddings via Paired Relation Vectors (2020) Difference within reported uncertainty; not counted as underperformance. |
Knowledge Graphs
| # | Model | MRR ↑ | Paper |
|---|---|---|---|
| 1 | FedSage | 0.8426
±0.0026 | |
| 2 | FED-PUB | 0.8348
±0.0025 | |
| 3 | FedAvg | 0.8252
±0.0023 | |
| 7 | GCN | 0.8171
±0.0030 | |
| 40 | HAKE | 0.4970 best reported | |
| 42 | ROTH | 0.4960 best reported | best at pub: Multi-hop Attention Graph Neural Networks (IJCAI 2020) |
| 43 | ConE | 0.4960 | This paper |
| 49 | ComplEx+RP | 0.4880 | This paper |
| 66 | Multi-Hop | 0.4720 | This paper |
| 77 | CURL | 0.4600 | This paper |
| # | Model | MRR ↑ | Paper |
|---|---|---|---|
| 1 | sum, Msg_r^3, f(t)=0 | 0.8500 | |
| 2 | sum, Msg_r^3, f(t)=t | 0.8440 | |
| 3 | PNA, Msg_r^1, f(t)=0 | 0.8010 | |
| 14 | Multi-Hop | 0.3930 | This paper |
| 15 | ComplEx+RP | 0.3880 | This paper |
| 50 | ConE | 0.3450 | This paper |
| 55 | HAKE | 0.3410 | This paper |
| 79 | CURL | 0.3060 | This paper |