Let Invariant Rationale Discovery Inspire Graph Contrastive Learning
Abstract
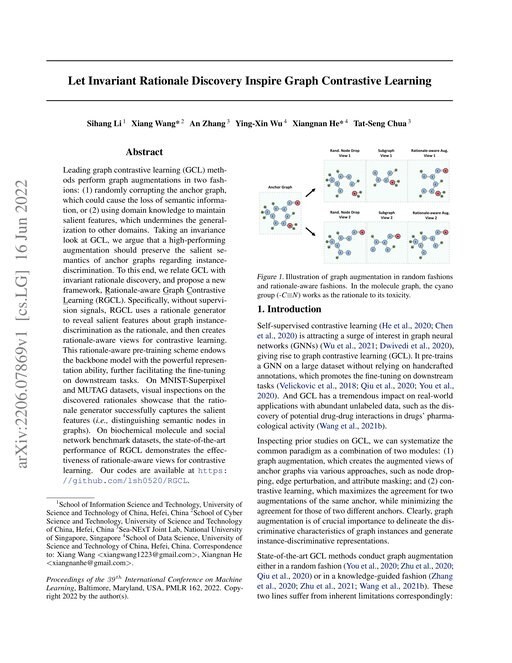
Leading graph contrastive learning (GCL) methods perform graph augmentations in two fashions: (1) randomly corrupting the anchor graph, which could cause the loss of semantic information, or (2) using domain knowledge to maintain salient features, which undermines the generalization to other domains. Taking an invariance look at GCL, we argue that a high-performing augmentation should preserve the salient semantics of anchor graphs regarding instance-discrimination. To this end, we relate GCL with invariant rationale discovery, and propose a new framework, Rationale-aware Graph Contrastive Learning (RGCL). Specifically, without supervision signals, RGCL uses a rationale generator to reveal salient features about graph instance-discrimination as the rationale, and then creates rationale-aware views for contrastive learning. This rationale-aware pre-training scheme endows the backbone model with the powerful representation ability, further facilitating the fine-tuning on downstream tasks. On MNIST-Superpixel and MUTAG datasets, visual inspections on the discovered rationales showcase that the rationale generator successfully captures the salient features (i.e. distinguishing semantic nodes in graphs). On biochemical molecule and social network benchmark datasets, the state-of-the-art performance of RGCL demonstrates the effectiveness of rationale-aware views for contrastive learning. Our codes are available at https://github.com/lsh0520/RGCL.
Benchmark Results
Tested on 8 datasets 4 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
TU Dortmund
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | MSH-GNN | 0.9910
±0.0030 | |
| 2 | ID-GNN+BEC | 0.9830
±0.0360 | |
| 3 | SupCosine | 0.9830
±0.0250 | |
| 39 | GIN | 0.9330
±0.0290 | |
| 178 | AD-GCL | 0.9028
±0.0401 best reported | best at pub: Graph Self-Supervised Learning: A Survey (2021) best today: Unifying Graph Contrastive Learning via Graph Message Augmentation (2024) Difference within reported uncertainty; not counted as underperformance. |
| 355 | RGCL | 0.8766
±0.0101 | This paper |
| 369 | No Pre-train | 0.8739
±0.0109 | This paper |
| 403 | MLP | 0.8660
±0.0495 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9954 | |
| 2 | GIN | 0.9934 | |
| 3 | GCN | 0.9727 | |
| 131 | GraphSAGE | 0.8200
±0.0100 | |
| 315 | RGCL | 0.7814
±0.0108 | This paper |
| 409 | AD-GCL | 0.7391
±0.0077 | prev best: Automated Data Augmentations for Graph Classification (ICLR 2022) best today: GIMM: InfoMin-Max for Automated Graph Contrastive Learning (2023) |
| 522 | No Pre-train | 0.6540
±0.0017 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9792 | |
| 2 | MSH-GNN | 0.9640
±0.0070 | |
| 3 | CoCN | 0.8722
±0.0013 | |
| 23 | GCN | 0.8260
±0.0220 | |
| 146 | InfoGraph | 0.7940 best reported | best at pub: CogDL: A Comprehensive Library for Graph Deep Learning (WWW 2021) |
| 151 | MLP | 0.7920
±0.0240 | |
| 233 | AD-GCL | 0.7582
±0.0026 best reported | best at pub: Graph Self-Supervised Learning: A Survey (2021) best today: Unifying Graph Contrastive Learning via Graph Message Augmentation (2024) |
| 271 | RGCL | 0.7348
±0.0093 best reported | best today: Graph Contrastive Learning with Cohesive Subgraph Awareness (WWW 2024) |
| 320 | No Pre-train | 0.6529
±0.0016 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | OEPG | 0.9630
±0.0090 | |
| 2 | MSH-GNN | 0.9580
±0.0090 | |
| 3 | GNN-AK+ | 0.9480
±0.0080 | |
| 13 | GIN | 0.9240
±0.0250 | |
| 26 | RGCL | 0.9138
±0.0040 best reported | best today: Graph Contrastive Learning with Cohesive Subgraph Awareness (WWW 2024) |
| 37 | AD-GCL | 0.9007
±0.0085 | prev best: Graph Self-Supervised Learning: A Survey (2021) |
| 77 | No Pre-train | 0.7686
±0.0025 | This paper |
MoleculeNet
| # | Model | ROC-AUC ↑ | Paper |
|---|---|---|---|
| 1 | ProtoMol | 0.9140
±0.0030 | |
| 2 | MMSG | 0.9080
±0.0050 | |
| 3 | MemGNN | 0.9070 | |
| 43 | GIN | 0.8646
±0.0081 | |
| 98 | GraphLoG | 0.8260
±0.0125 | prev best: 16 Pre-training Molecular Graph Representation with 3D Geometry (ICLR 2021) |
| 202 | AD-GCL | 0.7900
±0.0080 best reported | best today: Community-Invariant Graph Contrastive Learning (ICML 2024) |
| 242 | RGCL | 0.7603
±0.0077 | This paper |
| 281 | No Pre-train | 0.7010
±0.0540 | This paper |
| # | Model | ROC-AUC ↑ | Paper |
|---|---|---|---|
| 1 | SE(3)-I MPPH | 0.9930
±0.0040 | |
| 2 | KA-GCN | 0.9920
±0.0050 | |
| 3 | KA-GAT | 0.9910
±0.0050 | |
| 19 | GCN | 0.9130
±0.0170 | |
| 57 | RGCL | 0.8500
±0.0080 best reported | best today: Rethinking Tokenizer and Decoder in Masked Graph Modeling for Molecules (NeurIPS 2023) |
| 82 | AD-GCL | 0.8077
±0.0392 best reported | best today: Community-Invariant Graph Contrastive Learning (ICML 2024) Difference within reported uncertainty; not counted as underperformance. |
| 103 | GraphLoG | 0.7872
±0.0258 | prev best: 16 Pre-training Molecular Graph Representation with 3D Geometry (ICLR 2021) |
| # | Model | ROC-AUC ↑ | Paper |
|---|---|---|---|
| 1 | KA-GAT | 0.8470
±0.0020 | |
| 2 | KA-GCN | 0.8420
±0.0010 | |
| 3 | GraphKAN | 0.8370
±0.0010 | |
| 66 | GIN | 0.6403
±0.0104 | |
| 123 | GraphLoG | 0.6150
±0.0130 best reported | best at pub: KPGT: Knowledge-Guided Pre-training of Graph Transformer for Molecular Property Prediction (KDD 2022) |
| 128 | RGCL | 0.6140
±0.0060 best reported | best today: Dual-perspective Cross Contrastive Learning in Graph Transformers (2024) Difference within reported uncertainty; not counted as underperformance. |
| 146 | AD-GCL | 0.6080
±0.0090 best reported | best today: Community-Invariant Graph Contrastive Learning (ICML 2024) |
| # | Model | ROC-AUC ↑ | Paper |
|---|---|---|---|
| 1 | GeomGCL | 0.7630 | |
| 2 | LiGhT DeepGPT | 0.7570
±0.0110 | |
| 3 | CoMPT | 0.7550 | |
| 14 | GCN | 0.7350
±0.0020 | |
| 64 | GraphLoG | 0.6770
±0.0190 best reported | best at pub: KPGT: Knowledge-Guided Pre-training of Graph Transformer for Molecular Property Prediction (KDD 2022) |
| 138 | AD-GCL | 0.6350
±0.0070 best reported | best today: Community-Invariant Graph Contrastive Learning (ICML 2024) Difference within reported uncertainty; not counted as underperformance. |
| 142 | No Pre-train | 0.6340
±0.0060 | This paper |
| 148 | RGCL | 0.6333
±0.0017 | This paper |