Total Variation Graph Neural Networks
Abstract
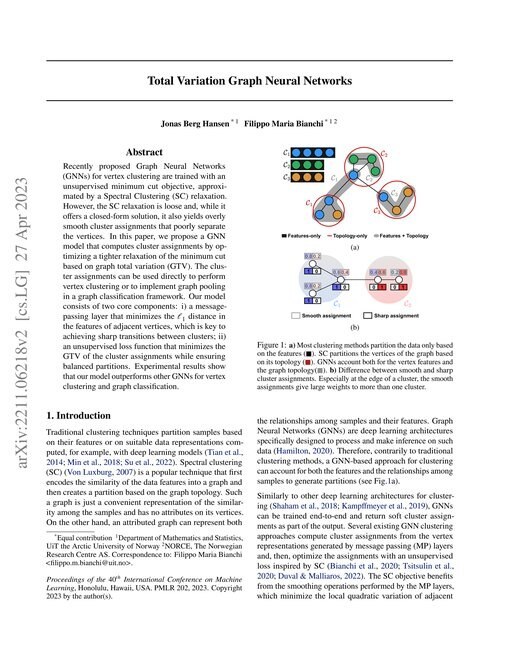
Recently proposed Graph Neural Networks (GNNs) for vertex clustering are trained with an unsupervised minimum cut objective, approximated by a Spectral Clustering (SC) relaxation. However, the SC relaxation is loose and, while it offers a closed-form solution, it also yields overly smooth cluster assignments that poorly separate the vertices. In this paper, we propose a GNN model that computes cluster assignments by optimizing a tighter relaxation of the minimum cut based on graph total variation (GTV). The cluster assignments can be used directly to perform vertex clustering or to implement graph pooling in a graph classification framework. Our model consists of two core components: i) a message-passing layer that minimizes the $ _1$ distance in the features of adjacent vertices, which is key to achieving sharp transitions between clusters; ii) an unsupervised loss function that minimizes the GTV of the cluster assignments while ensuring balanced partitions. Experimental results show that our model outperforms other GNNs for vertex clustering and graph classification.
Benchmark Results
Tested on 5 datasets 5 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
TU Dortmund
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | MSH-GNN | 0.9910
±0.0030 | |
| 2 | ID-GNN+BEC | 0.9830
±0.0360 | |
| 3 | SupCosine | 0.9830
±0.0250 | |
| 39 | GIN | 0.9330
±0.0290 | |
| 141 | MINCUTPOOL | 0.8520
±0.0720 | prev best: Structural Entropy Guided Graph Hierarchical Pooling (ICML 2022) Improvement within reported uncertainty; not highlighted. |
| 239 | DiffPool | 0.8640
±0.0760 | prev best: CogDL: A Comprehensive Library for Graph Deep Learning (WWW 2021) Improvement within reported uncertainty; not highlighted. |
| 317 | TVGNN | 0.8840
±0.0750 | This paper |
| 402 | DMoN | 0.8670
±0.0700 | This paper |
| 403 | MLP | 0.8660
±0.0495 | |
| 623 | SAGPool | 0.7986
±0.0236 best reported | best at pub: Embedding Graphs on Grassmann Manifold (2022) Difference within reported uncertainty; not counted as underperformance. |
| 641 | Top-k | 0.7920
±0.0800 best reported | best at pub: Graph Neural Networks in TensorFlow and Keras with Spektral (2020) Difference within reported uncertainty; not counted as underperformance. |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9954 | |
| 2 | GIN | 0.9934 | |
| 3 | GCN | 0.9727 | |
| 5 | DiffPool | 0.9210
±0.0260 best reported | best at pub: Contrastive Self-supervised Learning for Graph Classification (AAAI 2020) best today: Where to Mask: Structure-Guided Masking for Graph Masked Autoencoders (IJCAI 2024) |
| 131 | GraphSAGE | 0.8200
±0.0100 | |
| 259 | SAGPool | 0.7910
±0.0300 best reported | best at pub: Contrastive Self-supervised Learning for Graph Classification (AAAI 2020) best today: The expressive power of pooling in Graph Neural Networks (NeurIPS 2023) |
| 294 | DMoN | 0.7850
±0.0140 best reported | best today: The expressive power of pooling in Graph Neural Networks (NeurIPS 2023) |
| 348 | TVGNN | 0.7730
±0.0180 | This paper |
| 368 | MINCUTPOOL | 0.7680
±0.0160 best reported | best at pub: Higher-order Clustering and Pooling for Graph Neural Networks (2022) Difference within reported uncertainty; not counted as underperformance. |
| 457 | Top-k | 0.7260
±0.0310 best reported | best at pub: Graph Neural Networks in TensorFlow and Keras with Spektral (2020) best today: The expressive power of pooling in Graph Neural Networks (NeurIPS 2023) |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | MSH-GNN | 0.9410
±0.0330 | |
| 2 | GRDL | 0.8260
±0.0120 | |
| 3 | GMN | 0.8225 | |
| 7 | DiffPool | 0.8161
±0.0232 best reported | best at pub: Memory-Based Graph Networks (ICLR 2020) |
| 32 | GIN | 0.7880
±0.0410 | |
| 81 | TVGNN | 0.7710
±0.0290 | This paper |
| 149 | MLP | 0.7600
±0.0320 | |
| 154 | SAGPool | 0.7595
±0.0452 best reported | best at pub: Embedding Graphs on Grassmann Manifold (2022) Difference within reported uncertainty; not counted as underperformance. |
| 172 | MINCUTPOOL | 0.7575
±0.0380 best reported | best at pub: Pooling Architecture Search for Graph Classification (2021) Difference within reported uncertainty; not counted as underperformance. |
| 229 | DMoN | 0.7520
±0.0330 | This paper |
| 461 | Top-k | 0.6960
±0.0270 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9792 | |
| 2 | MSH-GNN | 0.9640
±0.0070 | |
| 3 | CoCN | 0.8722
±0.0013 | |
| 23 | GCN | 0.8260
±0.0220 | |
| 33 | DiffPool | 0.8213
±0.0043 best reported | best at pub: CogDL: A Comprehensive Library for Graph Deep Learning (WWW 2021) best today: Scalable Graph Compressed Convolutions (2024) |
| 39 | SAGPool | 0.8176
±0.0157 best reported | best at pub: Embedding Graphs on Grassmann Manifold (2022) |
| 86 | MINCUTPOOL | 0.8090
±0.0030 best reported | best at pub: Structural Entropy Guided Graph Hierarchical Pooling (ICML 2022) best today: Graph Classification via Reference Distribution Learning: Theory and Practice (NeurIPS 2024) Difference within reported uncertainty; not counted as underperformance. |
| 84 | DMoN | 0.8090
±0.0070 best reported | best today: The expressive power of pooling in Graph Neural Networks (NeurIPS 2023) |
| 135 | TVGNN | 0.7980
±0.0110 | This paper |
| 151 | MLP | 0.7920
±0.0240 | |
| 180 | Top-k | 0.7790
±0.0210 best reported | best today: The expressive power of pooling in Graph Neural Networks (NeurIPS 2023) Difference within reported uncertainty; not counted as underperformance. |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GC-GNN (GCN) | 0.9210
±0.0810 | |
| 2 | SUGAR | 0.8403
±0.0133 | |
| 3 | Ortho-g-U-Nets | 0.8387 | |
| 15 | SAGE | 0.8088
±0.0233 | |
| 18 | DiffPool | 0.8064 best reported | best at pub: Graph U-Nets (2019) best today: Orthogonal Graph Neural Networks (AAAI 2021) Difference within reported uncertainty; not counted as underperformance. |
| 34 | TVGNN | 0.7950
±0.0220 | This paper |
| 56 | SAGPool | 0.7870
±0.0229 best reported | best at pub: Contrastive Self-supervised Learning for Graph Classification (AAAI 2020) |
| 69 | MINCUTPOOL | 0.7822
±0.0054 best reported | best at pub: Structural Entropy Guided Graph Hierarchical Pooling (ICML 2022) best today: Cluster-wise Graph Transformer with Dual-granularity Kernelized Attention (NeurIPS 2024) Difference within reported uncertainty; not counted as underperformance. |
| 76 | DMoN | 0.7800
±0.0330 | This paper |
| 184 | Top-k | 0.6200
±0.0560 | This paper |