From Node Interaction to Hop Interaction: New Effective and Scalable Graph Learning Paradigm
Abstract
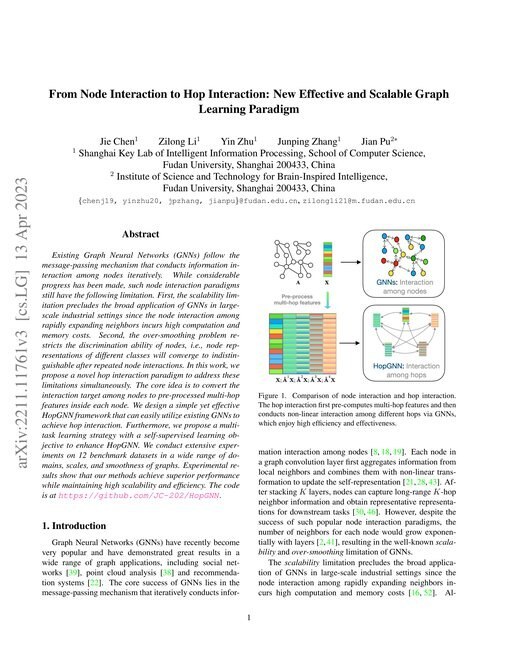
Existing Graph Neural Networks (GNNs) follow the message-passing mechanism that conducts information interaction among nodes iteratively. While considerable progress has been made, such node interaction paradigms still have the following limitation. First, the scalability limitation precludes the broad application of GNNs in large-scale industrial settings since the node interaction among rapidly expanding neighbors incurs high computation and memory costs. Second, the over-smoothing problem restricts the discrimination ability of nodes, i.e., node representations of different classes will converge to indistinguishable after repeated node interactions. In this work, we propose a novel hop interaction paradigm to address these limitations simultaneously. The core idea is to convert the interaction target among nodes to pre-processed multi-hop features inside each node. We design a simple yet effective HopGNN framework that can easily utilize existing GNNs to achieve hop interaction. Furthermore, we propose a multi-task learning strategy with a self-supervised learning objective to enhance HopGNN. We conduct extensive experiments on 12 benchmark datasets in a wide range of domains, scales, and smoothness of graphs. Experimental results show that our methods achieve superior performance while maintaining high scalability and efficiency. The code is at.
Benchmark Results
Tested on 9 datasets 35 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 21 | GCN | 0.9004 best reported | best at pub: SplineCNN: Fast Geometric Deep Learning with Continuous B-Spline Kernels (2017) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 25 | ACM-GCN | 0.8975
±0.0116 best reported | best today: Large Language Model Meets Graph Neural Network in Knowledge Distillation (AAAI 2024) Difference within reported uncertainty; not counted as underperformance. |
| 39 | SAGE | 0.8911
±0.0012 | |
| 44 | GAT | 0.8897
±0.0014 best reported | best at pub: Learned Low Precision Graph Neural Networks (2020) best today: Adaptive Tokenization: On the Hop-Overpriority Problem in Tokenized Graph Learning Models (2025) Difference within reported uncertainty; not counted as underperformance. |
| 45 | GCNII | 0.8893
±0.0137 best reported | best at pub: Orthogonal Graph Neural Networks (AAAI 2021) best today: Large Language Model Meets Graph Neural Network in Knowledge Distillation (AAAI 2024) Difference within reported uncertainty; not counted as underperformance. |
| 50 | FAGCN | 0.8885
±0.0136 best reported | best at pub: GPNet: Simplifying Graph Neural Networks via Multi-channel Geometric Polynomials (2022) best today: Large Language Model Meets Graph Neural Network in Knowledge Distillation (AAAI 2024) |
| 70 | DAGNN | 0.8840 best reported | best at pub: Tackling Over-Smoothing for General Graph Convolutional Networks (2020) Difference within reported uncertainty; not counted as underperformance. |
| 77 | GPRGNN | 0.8698
±0.0133 | prev best: Mixed Graph Contrastive Network for Semi-Supervised Node Classification (2022) |
| 82 | WRGAT | 0.8820
±0.0226 best reported | best today: Graph Neural Reaction Diffusion Models Submitted to the editors June 2023. Accepted in March 2024. (2024) Difference within reported uncertainty; not counted as underperformance. |
| 103 | GGCN | 0.8795
±0.0105 | This paper |
| 108 | APPNP | 0.8787 best reported | best at pub: Orthogonal Graph Neural Networks (AAAI 2021) best today: Feature Transportation Improves Graph Neural Networks (AAAI 2023) Difference within reported uncertainty; not counted as underperformance. |
| 111 | H2GCN-2 | 0.8781
±0.0135 | This paper |
| 112 | S2GC | 0.8773
±0.0290 | prev best: Contrastive Laplacian Eigenmaps (NeurIPS 2022) |
| 113 | MixHop | 0.8761
±0.0085 | prev best: Power up! Robust Graph Convolutional Network via Graph Powering (AAAI 2019) |
| 119 | HopGNN | 0.8757
±0.0133 | This paper |
| 131 | HopGNN+SCL | 0.8728
±0.0171 | This paper |
| 141 | GraphSAGE | 0.8690
±0.0104 | |
| 149 | H2GCN-1 | 0.8692
±0.0137 | This paper |
| 159 | GCN + JK | 0.8679
±0.0092 | This paper |
| 160 | GCN-Cheby | 0.8676
±0.0095 | prev best: Mixed Graph Contrastive Network for Semi-Supervised Node Classification (2022) |
| 161 | SIGN | 0.8672
±0.0137 | prev best: ROD: Reception-aware Online Distillation for Sparse Graphs (KDD 2021) |
| 215 | GEOM | 0.8527 | This paper |
| 724 | MLP | 0.7475
±0.0222 | prev best: Block Modeling-Guided Graph Convolutional Neural Networks (AAAI 2021) Improvement within reported uncertainty; not highlighted. |
| # | Model | F1 ↑ | Paper |
|---|---|---|---|
| 1 | EnGCN | 0.9714
±0.0003 | |
| 2 | SAGN+SLE | 0.9710 | |
| 3 | GAMLP(JK) | 0.9704
±0.0001 | |
| 4 | GraphSAINT | 0.9700 best reported | best at pub: SIGN: Scalable Inception Graph Neural Networks (2020) best today: LMC: Fast Training of GNNs via subgraph-wise sampling with Provable Convergence (ICLR 2023) |
| 5 | HopGNN | 0.9698
±0.0004 | This paper |
| 8 | SIGN | 0.9680 | This paper |
| 14 | GraphSAGE | 0.9660 best reported | best at pub: Accelerating Large Scale Real-Time GNN Inference using Channel Pruning (2021) |
| 23 | AS-GCN | 0.9640
±0.0010 | prev best: GraphSAINT: Graph Sampling Based Inductive Learning Method (ICLR 2019) |
| 48 | ClusterGCN | 0.9570 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 58 | GCN | 0.9530
±0.0010 best reported | best at pub: GraphMAE: Self-Supervised Masked Graph Autoencoders (KDD 2022) |
| 73 | SGC | 0.9490 | This paper |
| 83 | S2GC | 0.9404
±0.0003 | This paper |
| 91 | FastGCN | 0.9370 best reported | best at pub: FastGCN: Fast Learning with Graph Convolutional Networks via Importance Sampling (ICLR 2018) |
OGB
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | Jacobi | 0.8968 | |
| 2 | GPR | 0.8953 | |
| 3 | LEMP4HG | 0.8939 | |
| 4 | SAGE | 0.8933 | |
| 6 | GCN | 0.8868 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 64 | GraphSAINT | 0.8383
±0.0014 best reported | best at pub: Node Feature Extraction by Self-Supervised Multi-scale Neighborhood Prediction (ICLR 2021) |
| 77 | SIGN | 0.8310
±0.0080 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 83 | GraphSAGE | 0.8287 best reported | best at pub: A Comprehensive Study on Large-Scale Graph Training: Benchmarking and Rethinking (NeurIPS 2022) best today: Clustering as Reasoning: A $k$-Means Interpretation of Chain-of-Thought Graph Learning (ICML 2026) |
| 94 | SGC | 0.8220
±0.0090 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 143 | HopGNN | 0.8008
±0.0008 | This paper |
| 190 | ClusterGCN | 0.7897
±0.0033 | This paper |
| 232 | S2GC | 0.7684
±0.0020 | This paper |
| 308 | FastGCN | 0.7346
±0.0020 | This paper |
| 351 | MLP | 0.6605
±0.0020 |
Heterophilic Graphs
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | P^2GNN | 0.9672
±0.0147 | |
| 2 | DoG | 0.9660
±0.0210 | |
| 3 | GPF-plus | 0.9583
±0.0419 | |
| 5 | ACM-GCN | 0.8784
±0.0440 | best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Improvement within reported uncertainty; not highlighted. |
| 28 | GPRGNN | 0.9295
±0.0131 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) Difference within reported uncertainty; not counted as underperformance. |
| 34 | MLP | 0.9230
±0.0070 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) |
| 39 | GGCN | 0.9213
±0.0305 best reported | best at pub: Understanding convolution on graphs via energies (TMLR 2022) best today: Graph Wave Networks (WWW 2025) |
| 46 | APPNP | 0.9131
±0.0197 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: A Quasi-Wasserstein Loss for Learning Graph Neural Networks (WWW 2023) |
| 53 | GraphSAGE | 0.9000
±0.0365 best reported | best at pub: Graph Neural Networks Inspired by Classical Iterative Algorithms (ICML 2021) best today: Graph Neural Networks Need Cluster-Normalize-Activate Modules (NeurIPS 2024) Difference within reported uncertainty; not counted as underperformance. |
| 61 | FAGCN | 0.8961
±0.0152 best reported | best at pub: A Piece-wise Polynomial Filtering Approach for Graph Neural Networks (2021) best today: Node-oriented Spectral Filtering for Graph Neural Networks (2022) |
| 70 | GCNII | 0.8918
±0.0443 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: Piecewise Constant Spectral Graph Neural Network (TMLR 2025) |
| 72 | HopGNN | 0.8915
±0.0404 best reported | best today: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) Difference within reported uncertainty; not counted as underperformance. |
| 104 | WRGAT | 0.8362
±0.0550 | Improvement within reported uncertainty; not highlighted. |
| 150 | H2GCN-1 | 0.8486
±0.0677 | This paper |
| 189 | SAGE | 0.8269 | |
| 203 | H2GCN-2 | 0.8216
±0.0528 | This paper |
| 210 | HopGNN+SCL | 0.8165
±0.0747 | This paper |
| 211 | GAT | 0.8162
±0.0645 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: Equivariance Everywhere All At Once: A Recipe for Graph Foundation Models (2025) |
| 235 | GCN + JK | 0.8066
±0.0191 best reported | best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 257 | GCN | 0.7933
±0.0447 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: Graph Wave Networks (WWW 2025) |
| 276 | MixHop | 0.7784
±0.0773 | This paper |
| 285 | GCN-Cheby | 0.7730
±0.0407 | This paper |
| 319 | SIGN | 0.7514
±0.0794 | This paper |
| 386 | DAGNN | 0.7027
±0.0493 | |
| 407 | S2GC | 0.6865
±0.0805 | This paper |
| 417 | GEOM | 0.6757 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | P^2GNN | 0.9541
±0.0272 | |
| 2 | ACM-GCN | 0.8514
±0.0607 | best today: Heterophily-informed Message Passing (TMLR 2025) Improvement within reported uncertainty; not highlighted. |
| 3 | RF-GCN | 0.9429 | |
| 15 | GGCN | 0.9230
±0.0367 best reported | best at pub: Understanding convolution on graphs via energies (TMLR 2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Difference within reported uncertainty; not counted as underperformance. |
| 21 | APPNP | 0.9181
±0.0196 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: LON-GNN: Spectral GNNs with Learnable Orthonormal Basis (2023) |
| 22 | GPRGNN | 0.9157
±0.0196 best reported | best at pub: Comprehensive Graph Gradual Pruning for Sparse Training in Graph Neural Networks (2022) best today: Simplified PCNet with Robustness (2024) |
| 24 | MLP | 0.9136
±0.0070 best reported | best at pub: Is Homophily a Necessity for Graph Neural Networks? (ICLR 2021) best today: Node-oriented Spectral Filtering for Graph Neural Networks (2022) |
| 35 | GCNII | 0.8918
±0.0396 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 38 | FAGCN | 0.8852
±0.0133 best reported | best at pub: Comprehensive Graph Gradual Pruning for Sparse Training in Graph Neural Networks (2022) best today: Node-oriented Spectral Filtering for Graph Neural Networks (2022) |
| 104 | HopGNN+SCL | 0.8432
±0.0671 | This paper |
| 113 | HopGNN | 0.8405
±0.0448 | This paper |
| 138 | SAGE | 0.8269 | |
| 153 | H2GCN-1 | 0.8216
±0.0480 | This paper |
| 154 | H2GCN-2 | 0.8216
±0.0600 | This paper |
| 157 | GraphSAGE | 0.8196
±0.0739 best reported | best at pub: Graph-Coupled Oscillator Networks (ICML 2022) best today: Heterophily-Aware Graph Attention Network (2023) Difference within reported uncertainty; not counted as underperformance. |
| 158 | GAT | 0.8190
±0.0540 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 160 | WRGAT | 0.8162
±0.0390 | This paper |
| 170 | GCN | 0.8082
±0.0360 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: Bayesian Neighborhood Adaptation for Graph Neural Networks (TMLR 2025) |
| 183 | MixHop | 0.7950
±0.0630 best reported | best at pub: Label-Wise Graph Convolutional Network for Heterophilic Graphs (2021) Difference within reported uncertainty; not counted as underperformance. |
| 198 | SIGN | 0.7811
±0.0467 | This paper |
| 229 | S2GC | 0.7525
±0.0782 | This paper |
| 243 | GCN-Cheby | 0.7432
±0.0746 | This paper |
| 250 | DAGNN | 0.7351
±0.0718 | |
| 316 | GCN + JK | 0.6656
±0.1382 best reported | best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Difference within reported uncertainty; not counted as underperformance. |
| 371 | GEOM | 0.6081 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DiGGR | 0.4535
±0.0353 | |
| 2 | TRIGON | 0.4402
±0.0028 | |
| 3 | DoG | 0.4320
±0.0120 | |
| 16 | ACM-GCN | 0.4198
±0.0089 best reported | best at pub: ES-GNN: Generalizing Graph Neural Networks Beyond Homophily with Edge Splitting (2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 33 | SIGN | 0.4122
±0.0096 best reported | best today: Optimizing Polynomial Graph Filters: A Novel Adaptive Krylov Subspace Approach (WWW 2024) |
| 38 | GCNII | 0.4082
±0.0179 best reported | best at pub: Understanding convolution on graphs via energies (TMLR 2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 41 | APPNP | 0.4046
±0.0064 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: A Quasi-Wasserstein Loss for Learning Graph Neural Networks (WWW 2023) |
| 42 | MLP | 0.4026
±0.0108 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: Heterophily-Aware Graph Attention Network (2023) |
| 52 | GPRGNN | 0.3992
±0.0067 best reported | best at pub: Hierarchical Graph Transformer with Adaptive Node Sampling (NeurIPS 2022) best today: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) |
| 56 | FAGCN | 0.3970 best reported | best at pub: Beyond Low-frequency Information in Graph Convolutional Networks (AAAI 2021) |
| 61 | HopGNN | 0.3933
±0.0279 best reported | best today: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) Difference within reported uncertainty; not counted as underperformance. |
| 62 | GGCN | 0.3929
±0.0048 best reported | best at pub: Understanding convolution on graphs via energies (TMLR 2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Difference within reported uncertainty; not counted as underperformance. |
| 68 | GraphSAGE | 0.3899
±0.0085 best reported | best at pub: Hierarchical Graph Transformer with Adaptive Node Sampling (NeurIPS 2022) best today: A Quasi-Wasserstein Loss for Learning Graph Neural Networks (WWW 2023) |
| 75 | WRGAT | 0.3860
±0.0110 best reported | best at pub: ES-GNN: Generalizing Graph Neural Networks Beyond Homophily with Edge Splitting (2022) |
| 135 | GCN | 0.3690 best reported | best at pub: Beyond Low-frequency Information in Graph Convolutional Networks (AAAI 2021) |
| 146 | HopGNN+SCL | 0.3672
±0.0105 | This paper |
| 162 | MixHop | 0.3648
±0.0120 best reported | best at pub: Deformable Graph Transformer (2022) best today: Towards Deep Attention in Graph Neural Networks: Problems and Remedies (ICML 2023) |
| 182 | GAT | 0.3605
±0.0035 best reported | best at pub: Hierarchical Graph Transformer with Adaptive Node Sampling (NeurIPS 2022) |
| 190 | H2GCN-1 | 0.3594
±0.0130 best reported | best at pub: NCGNN: Node-Level Capsule Graph Neural Network for Semisupervised Classification (2020) best today: Steering Graph Neural Networks with Pinning Control (2023) Difference within reported uncertainty; not counted as underperformance. |
| 204 | H2GCN-2 | 0.3562
±0.0130 | This paper |
| 211 | DAGNN | 0.3551
±0.0110 | |
| 260 | GCN + JK | 0.3418
±0.0085 | This paper |
| 262 | S2GC | 0.3417
±0.0092 | This paper |
| 265 | GCN-Cheby | 0.3411
±0.0109 | This paper |
| 266 | GIN | 0.3410
±0.0030 | |
| 307 | GEOM | 0.3163 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | Hetero-S (GAT 8-layer) | 0.8693 | |
| 2 | Dir-GNN+CNA | 0.8586
±0.0180 | |
| 3 | GAT | 0.8560 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: The Heterophilic Snowflake Hypothesis: Training and Empowering GNNs for Heterophilic Graphs (KDD 2024) |
| 28 | ACM-GCN | 0.7476
±0.0220 best reported | best today: Directed Homophily-Aware Graph Neural Network (2025) |
| 47 | HopGNN | 0.7121
±0.0145 | This paper |
| 48 | GGCN | 0.7114
±0.0184 | This paper |
| 51 | HopGNN+SCL | 0.7045
±0.0103 | This paper |
| 52 | GCN | 0.7033 best reported | best at pub: Non-Local Graph Neural Networks (2020) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 72 | GPRGNN | 0.6748
±0.0040 best reported | best at pub: Simplifying approach to Node Classification in Graph Neural Networks (2021) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 79 | APPNP | 0.6670
±0.0270 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 91 | WRGAT | 0.6524
±0.0087 | This paper |
| 96 | GCN + JK | 0.6468
±0.0285 best reported | best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Difference within reported uncertainty; not counted as underperformance. |
| 103 | GCNII | 0.6386
±0.0304 | This paper |
| 107 | FAGCN | 0.6344
±0.0205 best reported | best at pub: Non-Local Graph Neural Networks (2020) |
| 108 | SAGE | 0.6340
±0.0300 | |
| 115 | GraphSAGE | 0.6215
±0.0042 best reported | best at pub: Hierarchical Graph Transformer with Adaptive Node Sampling (NeurIPS 2022) |
| 125 | GEOM | 0.6090 | This paper |
| 129 | MixHop | 0.6050
±0.0253 | This paper |
| 130 | SIGN | 0.6048
±0.0210 | This paper |
| 139 | H2GCN-2 | 0.5939
±0.0198 | This paper |
| 145 | S2GC | 0.5855
±0.0515 | This paper |
| 156 | H2GCN-1 | 0.5711
±0.0158 | This paper |
| 164 | GCN-Cheby | 0.5524
±0.0276 | This paper |
| 169 | MLP | 0.5429 best reported | best at pub: Block Modeling-Guided Graph Convolutional Neural Networks (AAAI 2021) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 223 | DAGNN | 0.4592
±0.0230 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | IBG-NN | 0.7763
±0.0179 | |
| 2 | Dir-GNN+CNA | 0.7747
±0.0128 | |
| 3 | DHGNN | 0.7684
±0.0161 | |
| 25 | ACM-GCN | 0.6740
±0.0221 best reported | best today: Directed Homophily-Aware Graph Neural Network (2025) |
| 33 | HopGNN | 0.6423
±0.0133 | This paper |
| 43 | HopGNN+SCL | 0.6142
±0.0198 | This paper |
| 46 | GCN | 0.6067 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 67 | GAT | 0.5630
±0.0220 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 68 | APPNP | 0.5590
±0.0290 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 69 | GGCN | 0.5567
±0.0187 best reported | best at pub: GPNet: Simplifying Graph Neural Networks via Multi-channel Geometric Polynomials (2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Difference within reported uncertainty; not counted as underperformance. |
| 76 | GPRGNN | 0.5435
±0.0087 best reported | best at pub: Simplifying approach to Node Classification in Graph Neural Networks (2021) best today: Directed Homophily-Aware Graph Neural Network (2025) |
| 78 | GCN + JK | 0.5340
±0.0190 best reported | best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 96 | WRGAT | 0.4885
±0.0078 | This paper |
| 112 | SIGN | 0.4559
±0.0140 best reported | best today: Optimizing Polynomial Graph Filters: A Novel Adaptive Krylov Subspace Approach (WWW 2024) |
| 120 | SAGE | 0.4460
±0.0130 | |
| 126 | GCN-Cheby | 0.4386
±0.0164 | This paper |
| 127 | MixHop | 0.4380
±0.0148 | This paper |
| 128 | GraphSAGE | 0.4378
±0.0190 best reported | best at pub: Simplifying approach to Node Classification in Graph Neural Networks (2021) best today: UniGAP: A Universal and Adaptive Graph Upsampling Approach to Mitigate Over-Smoothing in Node Classification Tasks (2024) Difference within reported uncertainty; not counted as underperformance. |
| 139 | FAGCN | 0.4259
±0.0069 best reported | best at pub: Gradient Gating for Deep Multi-Rate Learning on Graphs (ICLR 2022) best today: Graph Neural Reaction Diffusion Models Submitted to the editors June 2023. Accepted in March 2024. (2024) Difference within reported uncertainty; not counted as underperformance. |
| 150 | S2GC | 0.4163
±0.0098 | This paper |
| 172 | MLP | 0.3930
±0.0079 best reported | best at pub: Block Modeling-Guided Graph Convolutional Neural Networks (AAAI 2021) |
| 176 | GCNII | 0.3881
±0.0197 best reported | best at pub: GPNet: Simplifying Graph Neural Networks via Multi-channel Geometric Polynomials (2022) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) Difference within reported uncertainty; not counted as underperformance. |
| 182 | GEOM | 0.3814 | This paper |
| 186 | H2GCN-2 | 0.3790
±0.0202 | This paper |
| 203 | H2GCN-1 | 0.3642
±0.0189 | This paper |
| 223 | DAGNN | 0.3472
±0.0255 best reported |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DMD++ | 0.9190
±0.0260 | |
| 2 | F-GREAD-BS | 0.9059
±0.0380 | |
| 3 | APPNP | 0.9010
±0.0350 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: When Graph Neural Networks Meet Dynamic Mode Decomposition (ICLR 2024) |
| 5 | GPRGNN | 0.8990
±0.0300 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: When Graph Neural Networks Meet Dynamic Mode Decomposition (ICLR 2024) |
| 15 | ACM-GCN | 0.8843
±0.0322 | This paper |
| 29 | WRGAT | 0.8698
±0.0378 | This paper |
| 32 | GGCN | 0.8686
±0.0329 | This paper |
| 35 | H2GCN-1 | 0.8667
±0.0469 | This paper |
| 37 | MLP | 0.8629
±0.0450 best reported | best at pub: Is Homophily a Necessity for Graph Neural Networks? (ICLR 2021) Difference within reported uncertainty; not counted as underperformance. |
| 39 | H2GCN-2 | 0.8588
±0.0422 | This paper |
| 40 | HopGNN | 0.8569
±0.0543 | This paper |
| 51 | HopGNN+SCL | 0.8437
±0.0491 | This paper |
| 53 | GAT | 0.8430
±0.0370 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 60 | FAGCN | 0.8333 best reported | best today: Beyond Smoothing: Unsupervised Graph Representation Learning with Edge Heterophily Discriminating (AAAI 2022) Difference within reported uncertainty; not counted as underperformance. |
| 63 | GCN | 0.8310
±0.0320 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 69 | GraphSAGE | 0.8118
±0.0556 | This paper |
| 73 | SIGN | 0.8059
±0.0375 | This paper |
| 75 | GCNII | 0.8039
±0.0340 | prev best: Optimization-Induced Graph Implicit Nonlinear Diffusion (ICML 2022) Improvement within reported uncertainty; not highlighted. |
| 76 | MixHop | 0.8039 best reported | best today: The Heterophilic Snowflake Hypothesis: Training and Empowering GNNs for Heterophilic Graphs (KDD 2024) Difference within reported uncertainty; not counted as underperformance. |
| 81 | GCN-Cheby | 0.7941
±0.0446 | This paper |
| 86 | GIN | 0.7900
±0.0060 | |
| 111 | GCN + JK | 0.7431
±0.0643 | This paper |
| 119 | DAGNN | 0.7176
±0.0525 | This paper |
| 120 | S2GC | 0.7157
±0.0901 | This paper |
| 151 | GEOM | 0.6412 | This paper |