IJCAI--23 Formatting Instructions
Abstract
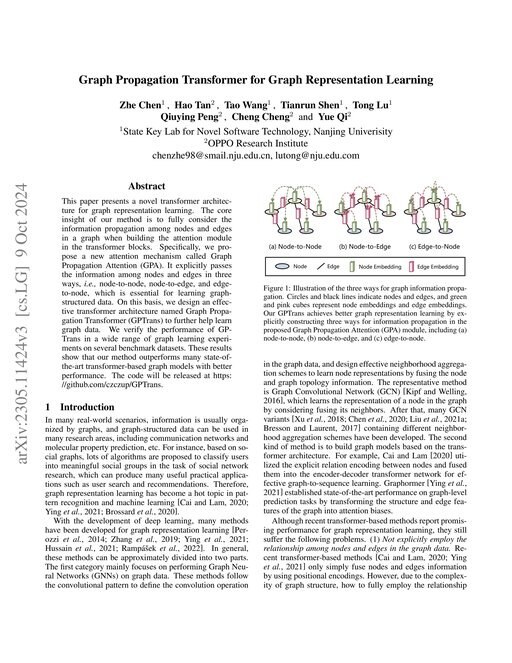
This paper presents a novel transformer architecture for graph representation learning. The core insight of our method is to fully consider the information propagation among nodes and edges in a graph when building the attention module in the transformer blocks. Specifically, we propose a new attention mechanism called Graph Propagation Attention (GPA). It explicitly passes the information among nodes and edges in three ways, node-to-node, node-to-edge, and edge-to-node, which is essential for learning graph-structured data. On this basis, we design an effective transformer architecture named Graph Propagation Transformer (GPTrans) to further help learn graph data. We verify the performance of GPTrans in a wide range of graph learning experiments on several benchmark datasets. These results show that our method outperforms many state-of-the-art transformer-based graph models with better performance. The code will be released at.
Benchmark Results
Tested on 3 datasets 4 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
OGB
| # | Model | MAE ↓ | Paper |
|---|---|---|---|
| 1 | DeMol | 0.0603 | |
| 2 | TGT-At | 0.0671 | |
| 3 | TGT-At (+RDKit) | 0.0683 | |
| 12 | GPTrans-L | 0.0809 | This paper |
| 13 | GPTrans-B | 0.0813 | This paper |
| 14 | GPTrans-S | 0.0823 | This paper |
| 16 | GPTrans-T | 0.0833 | This paper |
| 20 | GPS-Deep | 0.0852 | This paper |
| 22 | GPS-medium | 0.0858 | This paper |
| 26 | EGT-Larger | 0.0859 | This paper |
| 32 | GRPE-Large | 0.0867 | |
| 34 | EGT-Large | 0.0869 | prev best: GRPE: Relative Positional Encoding for Graph Transformer (2022) |
| 36 | EGT-Medium | 0.0881 | This paper |
| 38 | GraphormerV2-L | 0.0883 | This paper |
| 39 | GRPE-Standard | 0.0890 | prev best: GRPE: Relative Positional Encoding for Graph Transformer (2022) |
| 41 | EGT-Small | 0.0899 | This paper |
| 42 | Graphormer-B | 0.0906 | This paper |
| 43 | Graphormer-S | 0.0910 | This paper |
| 44 | TokenGT | 0.0910 | This paper |
| 50 | GPS-small | 0.0938 | This paper |
| 55 | DeeperGCN-VN | 0.1021 best reported | best at pub: One Transformer Can Understand Both 2D & 3D Molecular Data (ICLR 2022) best today: Enhancing Molecular Property Predictions by Learning from Bond Modelling and Interactions (ICLR 2026) |
| 58 | GIN-VN | 0.1083 | This paper |
| 60 | GCN-VN | 0.1152 | This paper |
| 62 | GINE-VN | 0.1167 best reported | best at pub: One Transformer Can Understand Both 2D & 3D Molecular Data (ICLR 2022) best today: Enhancing Molecular Property Predictions by Learning from Bond Modelling and Interactions (ICLR 2026) |
| 65 | GCN | 0.1195 best reported | best at pub: Recipe for a General, Powerful, Scalable Graph Transformer (NeurIPS 2022) best today: Enhancing Graph Neural Networks with Quantum Computed Encodings (2023) |
| 64 | GIN | 0.1195 | This paper |
| 78 | GT-Wide | 0.1408 | This paper |
GNNBenchmark
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GRPE-Small | 0.8159
±0.0019 | |
| 2 | TANGO-GPS | 0.8011
±0.0014 | |
| 3 | GRIT | 0.8003
±0.0028 | |
| 21 | GPTrans-Nano | 0.7807
±0.0015 | This paper |
| 54 | GatedGCN | 0.7608
±0.0020 | |
| 70 | GCN | 0.6903
±0.0137 | |
| 80 | GraphSAGE | 0.6388
±0.0011 | prev best: SoGCN: Second-Order Graph Convolutional Networks (2021) |
| 114 | MLP | 0.2097
±0.0000 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DeepGraph (48) | 0.9066
±0.0006 | |
| 2 | GRIT (our run) | 0.9041
±0.0023 | |
| 3 | GRIT 2-QiQRW | 0.9016
±0.0045 | |
| 24 | EGT | 0.8682
±0.0002 | This paper |
| 41 | GPTrans-Nano | 0.8673
±0.0008 | This paper |
| 54 | Graphormer-Slim | 0.8665
±0.0003 | This paper |
| 58 | SAN | 0.8658
±0.0004 | This paper |
| 66 | GatedGCN | 0.8651
±0.0008 | prev best: How Expressive are Transformers in Spectral Domain for Graphs? (TMLR 2022) |
| 88 | GCN | 0.8561
±0.0003 best reported | best at pub: GNNBenchmark (JMLR 2023) best today: Recurrent Distance Filtering for Graph Representation Learning (ICML 2023) |
| 89 | GIN | 0.8559
±0.0001 best reported | best at pub: Factorizable Graph Convolutional Networks (NeurIPS 2020) best today: GNNBenchmark (JMLR 2023) Difference within reported uncertainty; not counted as underperformance. |
| 95 | GT | 0.8481
±0.0007 | This paper |
| 107 | GAT | 0.7827
±0.0019 | This paper |
| 123 | MLP | 0.5052 | |
| 124 | GraphSAGE | 0.5052
±0.0000 best reported | best at pub: SoGCN: Second-Order Graph Convolutional Networks (2021) best today: GNNBenchmark (JMLR 2023) |