How Curvature Enhance the Adaptation Power of Framelet GCNs
Abstract
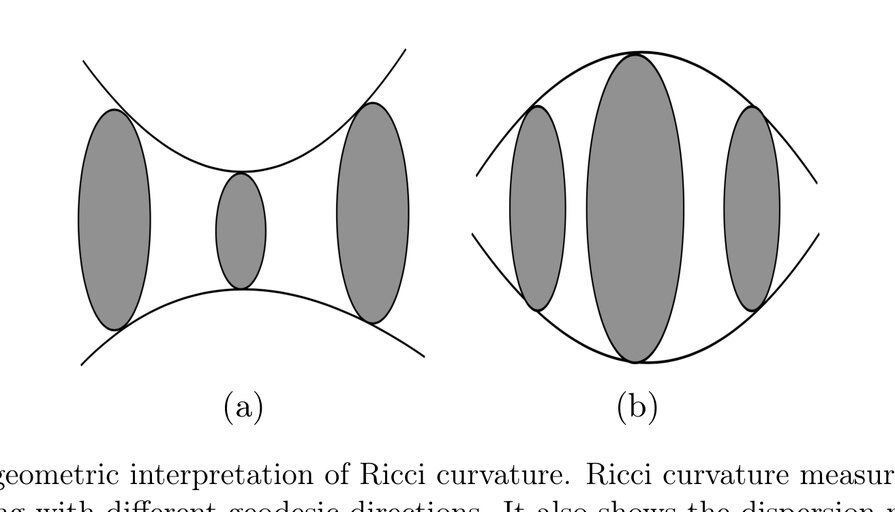
Graph neural network (GNN) has been demonstrated powerful in modeling graph-structured data. However, despite many successful cases of applying GNNs to various graph classification and prediction tasks, whether the graph geometrical information has been fully exploited to enhance the learning performance of GNNs is not yet well understood. This paper introduces a new approach to enhance GNN by discrete graph Ricci curvature. Specifically, the graph Ricci curvature defined on the edges of a graph measures how difficult the information transits on one edge from one node to another based on their neighborhoods. Motivated by the geometric analogy of Ricci curvature in the graph setting, we prove that by inserting the curvature information with different carefully designed transformation function $ $, several known computational issues in GNN such as over-smoothing can be alleviated in our proposed model. Furthermore, we verified that edges with very positive Ricci curvature (i.e., $ _i,j 1$) are preferred to be dropped to enhance model's adaption to heterophily graph and one curvature based graph edge drop algorithm is proposed. Comprehensive experiments show that our curvature-based GNN model outperforms the state-of-the-art baselines in both homophily and heterophily graph datasets, indicating the effectiveness of involving graph geometric information in GNNs.
Benchmark Results
Tested on 5 datasets 19 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 21 | GCN | 0.9004 | |
| 44 | GAT | 0.8897
±0.0014 best reported | best at pub: Learned Low Precision Graph Neural Networks (2020) |
| 55 | JKNet | 0.8870 best reported | best at pub: Learned Low Precision Graph Neural Networks (2020) |
| 77 | GPRGNN | 0.8826
±0.0050 best reported | |
| 265 | RC-UFG | 0.8440
±0.0070 | This paper |
| 350 | UFGConv_R | 0.8360
±0.0060 | This paper |
| 428 | UFGConv_S | 0.8300
±0.0050 | This paper |
| 458 | CurvGN | 0.8260
±0.0060 | prev best: Union Subgraph Neural Networks (AAAI 2023) |
| 508 | MoNet | 0.8220
±0.0070 best reported | best at pub: GRAND: Graph Neural Diffusion (ICML 2021) Difference within reported uncertainty; not counted as underperformance. |
| 724 | MLP | 0.7768 best reported | best at pub: From Node Interaction to Hop Interaction: New Effective and Scalable Graph Learning Paradigm (2022) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | CNA | 0.9575
±0.0058 | |
| 2 | IS-GIB | 0.9390
±0.0187 | |
| 3 | EERM | 0.9112
±0.0145 | |
| 20 | APPNP | 0.8142
±0.0026 best reported | best at pub: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 32 | GPRGNN | 0.8102
±0.0071 best reported | best at pub: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 35 | GAT | 0.8080
±0.0026 best reported | best at pub: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 44 | GCN | 0.8033
±0.0088 best reported | best at pub: Gophormer: Ego-Graph Transformer for Node Classification (2021) |
| 61 | GraphSAGE | 0.7923
±0.0053 | |
| 62 | JKNet | 0.7920 best reported | best at pub: Tackling Over-Smoothing for General Graph Convolutional Networks (2020) |
| 350 | MLP | 0.7289
±0.0010 best reported | best at pub: Block Modeling-Guided Graph Convolutional Neural Networks (AAAI 2021) best today: Gumbel-MPNN: Graph Rewiring with Gumbel-Softmax (2025) |
| 365 | UFGConv_R | 0.7270
±0.0060 | This paper |
| 400 | RC-UFG | 0.7250
±0.0070 | This paper |
| 506 | CurvGN | 0.7150
±0.0080 | prev best: Union Subgraph Neural Networks (AAAI 2023) |
| 540 | MoNet | 0.7120 | This paper |
| 556 | UFGConv_S | 0.7100
±0.0060 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | LGTL | 0.9518
±0.0011 | |
| 2 | MixHop (LO) | 0.9513
±0.0038 | |
| 3 | GraphSAGE (LO) | 0.9511
±0.0036 | |
| 18 | GCN | 0.9296
±0.0015 | |
| 20 | GAT | 0.9233
±0.0018 best reported | best at pub: Tackling Over-Smoothing for General Graph Convolutional Networks (2020) |
| 24 | JKNet | 0.9160 best reported | best at pub: Tackling Over-Smoothing for General Graph Convolutional Networks (2020) |
| 101 | GPRGNN | 0.8911
±0.0008 best reported | best at pub: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 210 | MLP | 0.8690
±0.0074 best reported | best at pub: Block Modeling-Guided Graph Convolutional Neural Networks (AAAI 2021) best today: On the Equivalence of Graph Convolution and Mixup (TMLR 2023) |
| 306 | RC-UFG | 0.8290
±0.0020 | This paper |
| 446 | MoNet | 0.8006
±0.0055 best reported | |
| 488 | UFGConv_R | 0.7960
±0.0040 | This paper |
| 525 | UFGConv_S | 0.7940
±0.0040 | This paper |
| 616 | CurvGN | 0.7880
±0.0060 | prev best: Union Subgraph Neural Networks (AAAI 2023) |
Heterophilic Graphs
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | P^2GNN | 0.9672
±0.0147 | |
| 2 | DoG | 0.9660
±0.0210 | |
| 3 | GPF-plus | 0.9583
±0.0419 | |
| 34 | MLP | 0.9230
±0.0070 | |
| 36 | MLP-2 | 0.9226
±0.0071 | This paper |
| 40 | H2GCN | 0.8590
±0.0353 | prev best: Graph-Coupled Oscillator Networks (ICML 2022) Improvement within reported uncertainty; not highlighted. |
| 53 | GraphSAGE | 0.9000
±0.0365 best reported | best at pub: Heterophily-Aware Graph Attention Network (2023) best today: Graph Neural Networks Need Cluster-Normalize-Activate Modules (NeurIPS 2024) |
| 189 | SAGE | 0.8269 | |
| 196 | UFG | 0.8230
±0.0090 best reported | best today: Unifying over-smoothing and over-squashing in graph neural networks: A physics informed approach and beyond (2023) Difference within reported uncertainty; not counted as underperformance. |
| 211 | GAT | 0.8162
±0.0645 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: Equivariance Everywhere All At Once: A Recipe for Graph Foundation Models (2025) Difference within reported uncertainty; not counted as underperformance. |
| 228 | RC-UFG (Het)_D | 0.8105
±0.0021 | This paper |
| 245 | RC-UFG | 0.7996
±0.0138 | This paper |
| 298 | Mixhp | 0.7639
±0.0766 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | IBG-NN | 0.7763
±0.0179 | |
| 2 | Dir-GNN+CNA | 0.7747
±0.0128 | |
| 3 | DHGNN | 0.7684
±0.0161 | |
| 39 | H2GCN | 0.6190
±0.0140 best reported | best at pub: Optimization-Induced Graph Implicit Nonlinear Diffusion (ICML 2022) best today: Efficient Learning on Large Graphs using a Densifying Regularity Lemma (2025) |
| 46 | GCN | 0.6067 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) best today: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 67 | GAT | 0.5630
±0.0220 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 68 | APPNP | 0.5590
±0.0290 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 104 | RC-UFG (Het)_D | 0.4658
±0.0044 | This paper |
| 120 | SAGE | 0.4460
±0.0130 | |
| 122 | RC-UFG | 0.4453
±0.0153 | This paper |
| 124 | UFG | 0.4428
±0.0091 | This paper |
| 128 | GraphSAGE | 0.4378
±0.0190 best reported | best at pub: Simplifying approach to Node Classification in Graph Neural Networks (2021) best today: UniGAP: A Universal and Adaptive Graph Upsampling Approach to Mitigate Over-Smoothing in Node Classification Tasks (2024) Difference within reported uncertainty; not counted as underperformance. |
| 172 | MLP | 0.3930
±0.0079 | |
| 237 | MLP-2 | 0.3128
±0.0027 | This paper |
| 266 | Mixhp | 0.2455
±0.0260 | This paper |