Self-Contrastive Graph Diffusion Network
Abstract
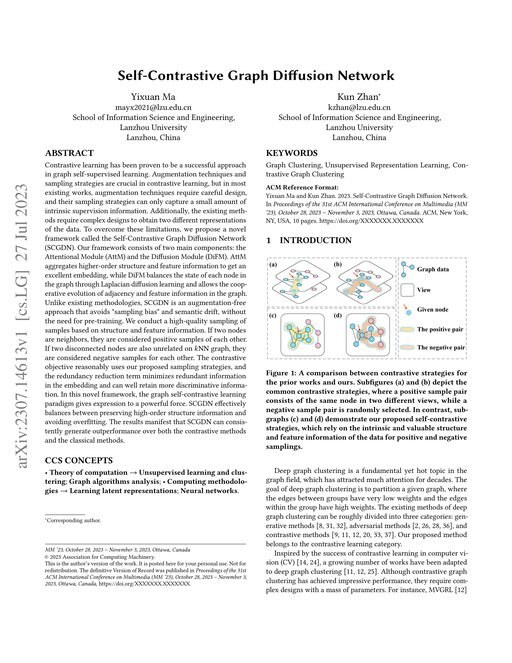
Contrastive learning has been proven to be a successful approach in graph self-supervised learning. Augmentation techniques and sampling strategies are crucial in contrastive learning, but in most existing works, augmentation techniques require careful design, and their sampling strategies can only capture a small amount of intrinsic supervision information. Additionally, the existing methods require complex designs to obtain two different representations of the data. To overcome these limitations, we propose a novel framework called the Self-Contrastive Graph Diffusion Network (SCGDN). Our framework consists of two main components: the Attentional Module (AttM) and the Diffusion Module (DiFM). AttM aggregates higher-order structure and feature information to get an excellent embedding, while DiFM balances the state of each node in the graph through Laplacian diffusion learning and allows the cooperative evolution of adjacency and feature information in the graph. Unlike existing methodologies, SCGDN is an augmentation-free approach that avoids "sampling bias" and semantic drift, without the need for pre-training. We conduct a high-quality sampling of samples based on structure and feature information. If two nodes are neighbors, they are considered positive samples of each other. If two disconnected nodes are also unrelated on $k$NN graph, they are considered negative samples for each other. The contrastive objective reasonably uses our proposed sampling strategies, and the redundancy reduction term minimizes redundant information in the embedding and can well retain more discriminative information. In this novel framework, the graph self-contrastive learning paradigm gives expression to a powerful force. SCGDN effectively balances between preserving high-order structure information and avoiding overfitting. The results manifest that SCGDN can consistently generate outperformance over both the contrastive methods and the classical methods.
Benchmark Results
Tested on 3 datasets 6 baseline values reported too low Non-standard metric on 1 dataset
Tables show presented results in global context (best 3 papers + GCN + MLP).
Hypergraph Benchmarks
AMAP
Global leaderboard →Sorted by F1. Highlighted rows are from other papers.
| # | Model | F1 ↑ | Paper |
|---|---|---|---|
| 1 | GANN | 0.9405
±0.0037 | |
| 2 | GPRGNN | 0.9308
±0.0026 | |
| 3 | GAT | 0.9238
±0.0014 | |
| 14 | GCN | 0.8115
±0.0105 | |
| 16 | DFCN | 0.7600
±0.0080 best reported | best at pub: Improved Dual Correlation Reduction Network (2022) |
| 17 | SCGDN | 0.7527
±0.0018 | This paper |
| 24 | AGC-DRR | 0.7103
±0.0064 | This paper |
| 25 | AFGRL | 0.6999
±0.0034 | This paper |
| 26 | DAEGC | 0.6987
±0.0054 | This paper |
| 30 | MGAE | 0.6808
±0.0176 | This paper |
| 41 | AutoSSL | 0.5447
±0.0083 | This paper |
| 50 | MVGRL | 0.4600 best reported | best at pub: Improved Dual Correlation Reduction Network (2022) best today: CDC: A Simple Framework for Complex Data Clustering (2024) |
| 51 | GDCL | 0.3837
±0.0029 | This paper |
| 53 | ProGCL | 0.3197
±0.0044 | This paper |
| # | Model | F1 ↑ | Paper |
|---|---|---|---|
| 1 | GraphLearner | 0.7540
±0.0088 | |
| 2 | SCGDN | 0.7449
±0.0026 | This paper |
| 3 | SCGC | 0.7222
±0.0097 | |
| 7 | MVGRL | 0.7047
±0.0370 best reported | best at pub: Simple Contrastive Graph Clustering (2022) |
| 8 | DAEGC | 0.6987
±0.0054 best reported | best at pub: Simple Contrastive Graph Clustering (2022) |
| 11 | ProGCL | 0.5608
±0.0089 | This paper |
| 17 | DFCN | 0.5090
±0.0012 | This paper |
| 18 | MGAE | 0.5083
±0.0323 | This paper |
| 21 | AFGRL | 0.4653
±0.0057 | This paper |
| 24 | AGC-DRR | 0.4233
±0.0051 | This paper |
| 25 | GDCL | 0.3994
±0.0057 | This paper |
| 28 | AutoSSL | 0.3484
±0.0015 | This paper |
| # | Model | F1 ↑ | Paper |
|---|---|---|---|
| 1 | SCAGC | 0.7277
±0.0016 | |
| 2 | SCGC | 0.7222
±0.0097 | |
| 3 | AGE | 0.7174
±0.0093 | |
| 4 | DFCN | 0.7125
±0.0031 best reported | best at pub: Simple Contrastive Graph Clustering (2022) |
| 5 | DAEGC | 0.6987
±0.0054 best reported | best at pub: Simple Contrastive Graph Clustering (2022) |
| 8 | SCGDN | 0.5763
±0.0010 | This paper |
| 17 | MVGRL | 0.4700
±0.0600 best reported | best at pub: Simple Contrastive Graph Clustering (2022) best today: Non-Dissipative Graph Propagation for Non-Local Community Detection (2025) |
| 21 | MGAE | 0.4308
±0.0326 | prev best: Hard Sample Aware Network for Contrastive Deep Graph Clustering [5] (AAAI 2022) Improvement within reported uncertainty; not highlighted. |
| 22 | ProGCL | 0.4254
±0.0045 | This paper |
| 24 | AGC-DRR | 0.3520
±0.0017 | This paper |
| 28 | AFGRL | 0.3053
±0.0147 | This paper |
| 29 | GDCL | 0.2502
±0.0021 | This paper |
| 31 | AutoSSL | 0.2182
±0.0098 | This paper |