Mixture of Weak & Strong Experts on Graphs
Abstract
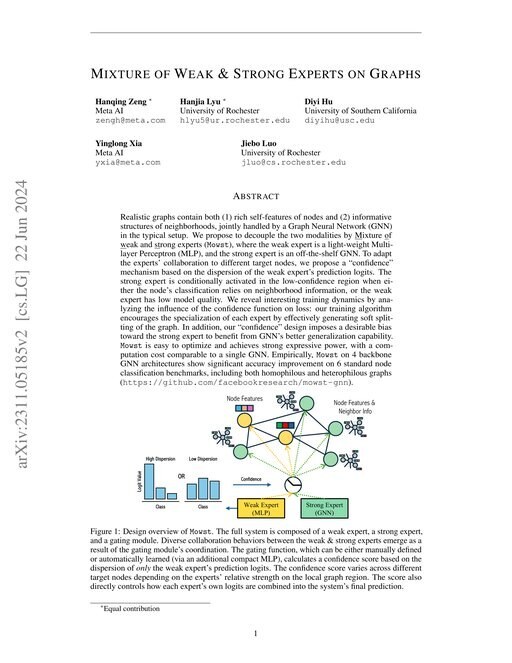
Realistic graphs contain both [(1)] rich self-features of nodes and [(2)] informative structures of neighborhoods, jointly handled by a Graph Neural Network (GNN) in the typical setup. We propose to decouple the two modalities by ixture f eak and rong experts (Mowst), where the weak expert is a light-weight Multi-layer Perceptron (MLP), and the strong expert is an off-the-shelf GNN. To adapt the experts' collaboration to different target nodes, we propose a ``confidence'' mechanism based on the dispersion of the weak expert's prediction logits. The strong expert is conditionally activated in the low-confidence region when either the node's classification relies on neighborhood information, or the weak expert has low model quality. We reveal interesting training dynamics by analyzing the influence of the confidence function on loss: our training algorithm encourages the specialization of each expert by effectively generating soft splitting of the graph. In addition, our ``confidence'' design imposes a desirable bias toward the strong expert to benefit from GNN's better generalization capability. Mowst is easy to optimize and achieves strong expressive power, with a computation cost comparable to a single GNN. Empirically, Mowst on 4 backbone GNN architectures show significant accuracy improvement on 6 standard node classification benchmarks, including both homophilous and heterophilous graphs.
Benchmark Results
Tested on 4 datasets SOTA at publication on 1 7 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
OGB
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | Jacobi | 0.8968 | |
| 2 | GPR | 0.8953 | |
| 3 | LEMP4HG | 0.8939 | |
| 4 | SAGE | 0.8933 best reported | best at pub: Learning on Large-scale Text-attributed Graphs via Variational Inference (ICLR 2022) |
| 6 | GCN | 0.8868 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 83 | GraphSAGE | 0.8287 | |
| 220 | GraphMoE-SAGE | 0.7779 | This paper |
| 238 | AdaGCN | 0.7641 best reported | best at pub: A Comprehensive Study on Large-Scale Graph Training: Benchmarking and Rethinking (NeurIPS 2022) |
| 301 | GraphMoE-GCN | 0.7390 | This paper |
| 315 | GPR-GNN | 0.7241
±0.0004 | This paper |
| 351 | MLP | 0.6605
±0.0020 |
LINKX Benchmarks
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DC-GNN | 0.8669
±0.0022 | |
| 2 | M2M-GNN | 0.8594
±0.0040 | |
| 3 | GloGNN | 0.8574
±0.0042 | |
| 12 | MoE-GIN | 0.8456
±0.0031 | This paper |
| 20 | GPR-GNN | 0.8354
±0.0032 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: Optimizing Polynomial Graph Filters: A Novel Adaptive Krylov Subspace Approach (WWW 2024) |
| 21 | MoE-H2GCN | 0.8339
±0.0043 | This paper |
| 24 | H2GCN | 0.8320
±0.0055 best reported | best at pub: Clarify Confused Nodes via Separated Learning (2023) Difference within reported uncertainty; not counted as underperformance. |
| 25 | MoE-GCN | 0.8319
±0.0043 | This paper |
| 29 | GIN | 0.8268
±0.0032 | This paper |
| 31 | GCN | 0.8247
±0.0027 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) Difference within reported uncertainty; not counted as underperformance. |
| 35 | GraphMoE-GCN | 0.8161
±0.0027 | This paper |
| 36 | GAT | 0.8153
±0.0055 | prev best: Uplifting Message Passing Neural Network with Graph Original Information (2022) Improvement within reported uncertainty; not highlighted. |
| 41 | GIN-skip | 0.8032
±0.0043 | This paper |
| 42 | MoE-GIN-skip | 0.8032
±0.0043 | This paper |
| 44 | MoE-SAGE | 0.7907
±0.0043 | This paper |
| 45 | GraphMoE-SAGE | 0.7704
±0.0055 | This paper |
| 47 | GraphSAGE | 0.7675
±0.0052 | This paper |
| 50 | GCN-skip | 0.7658
±0.0053 | This paper |
| 51 | MLP | 0.7534
±0.0064 | |
| 53 | AdaGCN | 0.7442
±0.0058 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | SAGE | 0.8597
±0.0021 | |
| 2 | Polynormer | 0.8595
±0.0007 | |
| 3 | NID_SAGE | 0.8563
±0.0031 | |
| 4 | MoE-H2GCN | 0.8302
±0.0030 | This paper |
| 12 | H2GCN | 0.8089
±0.0016 | This paper |
| 13 | GPR-GNN | 0.8074
±0.0022 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: Graph Neural Networks with Learnable and Optimal Polynomial Bases (ICML 2023) |
| 15 | MoE-GIN-skip | 0.7970
±0.0023 | This paper |
| 17 | MoE-SAGE | 0.7784
±0.0004 | This paper |
| 18 | MoE-GCN | 0.7728
±0.0008 | This paper |
| 19 | GraphMoE-GCN | 0.7699
±0.0010 | This paper |
| 20 | GraphMoE-SAGE | 0.7667
±0.0008 | This paper |
| 21 | GIN-skip | 0.7629
±0.0051 | This paper |
| 22 | MoE-GIN | 0.7611
±0.0039 | This paper |
| 23 | GCN | 0.7601
±0.0049 | prev best: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) |
| 24 | GraphSAGE | 0.7576
±0.0004 | This paper |
| 26 | GCN-skip | 0.7346
±0.0004 | This paper |
| 28 | GAT | 0.7177
±0.0618 | prev best: FMP: Toward Fair Graph Message Passing against Topology Bias (2022) Improvement within reported uncertainty; not highlighted. |
| 31 | MLP | 0.7048
±0.0077 | |
| 41 | AdaGCN | 0.5592
±0.0035 | This paper |
| 42 | GIN | 0.5337
±0.0215 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DGT | 0.6609
±0.0022 | |
| 2 | ICG_u-NN | 0.6608
±0.0074 | |
| 3 | LINKX | 0.6606
±0.0019 | |
| 4 | MoE-H2GCN | 0.6603
±0.0016 | This paper |
| 5 | H2GCN | 0.6570
±0.0020 | This paper |
| 12 | MoE-GIN-skip | 0.6491
±0.0022 | This paper |
| 14 | GraphSAGE | 0.6473
±0.0011 best reported | best at pub: Deformable Graph Transformer (2022) |
| 15 | MoE-SAGE | 0.6438
±0.0014 | This paper |
| 16 | GCN | 0.6434
±0.0012 best reported | best at pub: Deformable Graph Transformer (2022) |
| 17 | MoE-GIN | 0.6432
±0.0034 | This paper |
| 21 | MoE-GCN | 0.6374
±0.0023 | This paper |
| 22 | GraphMoE-SAGE | 0.6342
±0.0023 | This paper |
| 25 | GAT | 0.6290
±0.0022 best reported | best at pub: Deformable Graph Transformer (2022) Difference within reported uncertainty; not counted as underperformance. |
| 26 | GraphMoE-GCN | 0.6276
±0.0022 | This paper |
| 27 | GPR-GNN | 0.6259
±0.0038 best reported | best at pub: Convolutional Neural Networks on Graphs with Chebyshev Approximation, Revisited (NeurIPS 2022) best today: Graph Neural Networks with Learnable and Optimal Polynomial Bases (ICML 2023) |
| 30 | GIN | 0.6176
±0.0060 | This paper |
| 33 | MLP | 0.6114
±0.0006 best reported | best at pub: Deformable Graph Transformer (2022) |
| 35 | GCN-skip | 0.6105
±0.0023 | This paper |
| 36 | AdaGCN | 0.6102
±0.0014 | This paper |