Recurrent Distance Filtering for Graph Representation Learning
Abstract
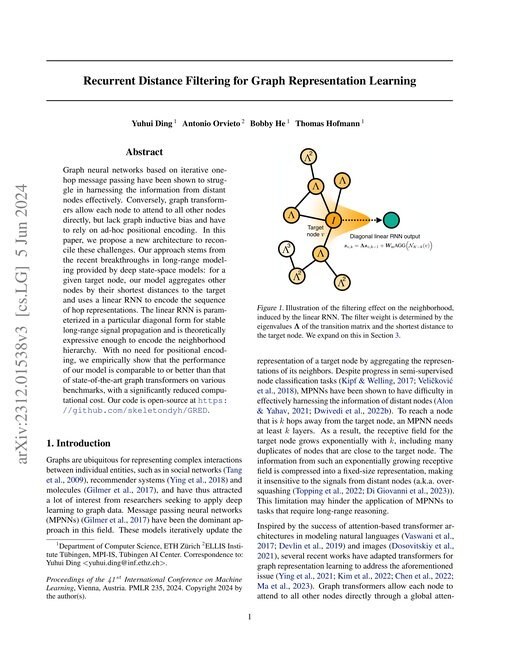
Graph neural networks based on iterative one-hop message passing have been shown to struggle in harnessing the information from distant nodes effectively. Conversely, graph transformers allow each node to attend to all other nodes directly, but lack graph inductive bias and have to rely on ad-hoc positional encoding. In this paper, we propose a new architecture to reconcile these challenges. Our approach stems from the recent breakthroughs in long-range modeling provided by deep state-space models: for a given target node, our model aggregates other nodes by their shortest distances to the target and uses a linear RNN to encode the sequence of hop representations. The linear RNN is parameterized in a particular diagonal form for stable long-range signal propagation and is theoretically expressive enough to encode the neighborhood hierarchy. With no need for positional encoding, we empirically show that the performance of our model is comparable to or better than that of state-of-the-art graph transformers on various benchmarks, with a significantly reduced computational cost. Our code is open-source at https://github.com/skeletondyh/GRED.
Benchmark Results
Tested on 6 datasets
Tables show presented results in global context (best 3 papers + GCN + MLP).
LRGB
| # | Model | MAE ↓ | Paper |
|---|---|---|---|
| 1 | GCN | 0.2421
±0.0016 | |
| 2 | IPR-MPNN | 0.2422
±0.0007 | |
| 3 | TANGO-GPS | 0.2422
±0.0014 | |
| 5 | GIN | 0.2429
±0.0019 | |
| 27 | GRED | 0.2455
±0.0013 best reported | best today: Molecular fingerprints are strong models for peptide function prediction (2025) |
| 32 | GRIT | 0.2460
±0.0012 | This paper |
| 56 | Graph-MLPMixer | 0.2475
±0.0015 | This paper |
| 85 | GPS | 0.2500
±0.0005 | prev best: Where Did the Gap Go? Reassessing the Long-Range Graph Benchmark (TMLR 2023) Improvement within reported uncertainty; not highlighted. |
| 115 | DRew | 0.2536
±0.0015 best reported | best today: Cooperative Sheaf Neural Networks (ICLR 2025) |
| 122 | PathNN | 0.2540
±0.0046 | This paper |
| 201 | MLP | 0.4351
±0.0008 |
| # | Model | AP ↑ | Paper |
|---|---|---|---|
| 1 | S^2GCN | 0.7311
±0.0066 | |
| 2 | S4G | 0.7293
±0.0004 | |
| 3 | BuNN | 0.7276
±0.0065 | |
| 4 | GCN | 0.7261
±0.0011 | |
| 13 | DRew | 0.7150
±0.0044 best reported | best today: Plain Transformers Can be Powerful Graph Learners (2025) |
| 14 | DRew+LapPE | 0.7150
±0.0044 | This paper |
| 16 | GRED+LapPE | 0.7133
±0.0011 | This paper |
| 21 | GRED | 0.7085
±0.0027 | This paper |
| 36 | GRIT | 0.6988
±0.0082 | This paper |
| 56 | PathNN | 0.6816
±0.0026 | This paper |
| 87 | GPS | 0.6562
±0.0115 best reported | best at pub: A Generalization of ViT/MLP-Mixer to Graphs (ICML 2022) Difference within reported uncertainty; not counted as underperformance. |
| 181 | MLP | 0.4060
±0.0021 |
GNNBenchmark
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | Schrödinger | 0.9913
±0.0004 | |
| 2 | CNN | 0.9907
±0.0007 | |
| 3 | MPNN | 0.9895
±0.0006 | |
| 11 | GatedGCN | 0.9855
±0.0002 | |
| 27 | GRED | 0.9838
±0.0001 | This paper |
| 30 | Graph MLP-Mixer | 0.9835
±0.0010 best reported | Difference within reported uncertainty; not counted as underperformance. |
| 32 | GIN | 0.9833
±0.0011 | |
| 56 | GRIT | 0.9811
±0.0011 | This paper |
| 126 | MLP | 0.9534
±0.0014 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | RandAlign | 0.7942
±0.0007 | |
| 2 | differential encoding | 0.7907
±0.0027 | |
| 3 | PPGT | 0.7856
±0.0070 | |
| 5 | GRED | 0.7685
±0.0019 | This paper |
| 30 | Graph MLP-Mixer | 0.7396
±0.0033 | This paper |
| 62 | GatedGCN | 0.7133
±0.0039 | |
| 92 | GraphSAGE | 0.6690
±0.0020 | |
| 126 | MLP | 0.5634
±0.0018 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GRPE-Small | 0.8159
±0.0019 | |
| 2 | TANGO-GPS | 0.8011
±0.0014 | |
| 3 | GRIT | 0.8003
±0.0028 | |
| 11 | GRED | 0.7850
±0.0010 | This paper |
| 25 | SAT | 0.7786
±0.0010 | This paper |
| 54 | GatedGCN | 0.7608
±0.0020 | |
| 70 | GCN | 0.6903
±0.0137 | prev best: How Expressive are Transformers in Spectral Domain for Graphs? (TMLR 2022) Improvement within reported uncertainty; not highlighted. |
| 79 | GIN | 0.6472
±0.0155 | |
| 114 | MLP | 0.2097
±0.0000 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DeepGraph (48) | 0.9066
±0.0006 | |
| 2 | GRIT (our run) | 0.9041
±0.0023 | |
| 3 | GRIT 2-QiQRW | 0.9016
±0.0045 | |
| 6 | GRIT | 0.8722
±0.0003 best reported | best today: Benchmarking Positional Encodings for GNNs and Graph Transformers (KDD 2024) Difference within reported uncertainty; not counted as underperformance. |
| 22 | SAT | 0.8685
±0.0004 | This paper |
| 34 | GRED | 0.8676
±0.0200 best reported | best today: Graph Mamba: Towards Learning on Graphs with State Space Models (KDD 2024) Difference within reported uncertainty; not counted as underperformance. |
| 66 | GatedGCN | 0.8651
±0.0008 | |
| 88 | GCN | 0.8561
±0.0003 | prev best: GNNBenchmark (JMLR 2023) |
| 89 | GIN | 0.8559
±0.0001 | |
| 123 | MLP | 0.5052 |