Fully-inductive Node Classification on Arbitrary Graphs
Abstract
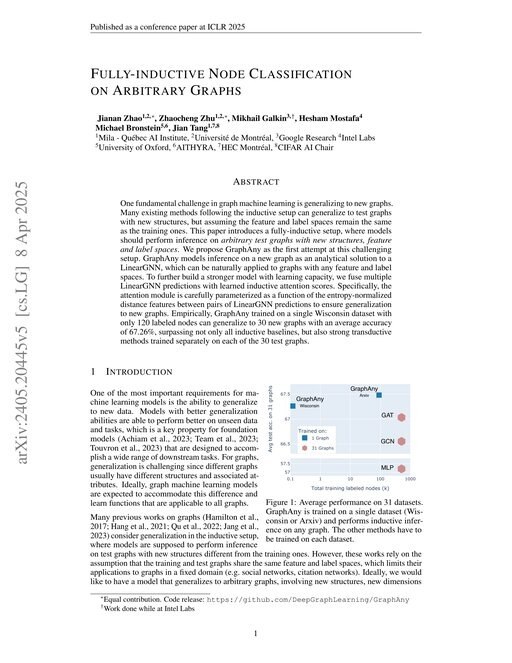
One fundamental challenge in graph machine learning is generalizing to new graphs. Many existing methods following the inductive setup can generalize to test graphs with new structures, but assuming the feature and label spaces remain the same as the training ones. This paper introduces a fully-inductive setup, where models should perform inference on arbitrary test graphs with new structures, feature and label spaces. We propose GraphAny as the first attempt at this challenging setup. GraphAny models inference on a new graph as an analytical solution to a LinearGNN, which can be naturally applied to graphs with any feature and label spaces. To further build a stronger model with learning capacity, we fuse multiple LinearGNN predictions with learned inductive attention scores. Specifically, the attention module is carefully parameterized as a function of the entropy-normalized distance features between pairs of LinearGNN predictions to ensure generalization to new graphs. Empirically, GraphAny trained on a single Wisconsin dataset with only 120 labeled nodes can generalize to 30 new graphs with an average accuracy of 67.26\
Benchmark Results
Tested on 6 datasets 11 baseline values reported too low Non-standard metric on 2 datasets
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 21 | GCN | 0.9004 best reported | best at pub: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 39 | SAGE | 0.8911
±0.0012 | |
| 44 | GAT | 0.8897
±0.0014 best reported | best at pub: Learned Low Precision Graph Neural Networks (2020) |
| 712 | LinearSGC2 | 0.7820 | This paper |
| 724 | MLP | 0.7768 best reported | best at pub: Understanding Heterophily for Graph Neural Networks (ICML 2024) |
| 784 | LinearSGC1 | 0.7430 | This paper |
| 802 | Linear | 0.7237
±0.0033 best reported | |
| 876 | LabelProp | 0.6030 | This paper |
| 919 | LinearHGC2 | 0.2380 | This paper |
| 921 | LinearHGC1 | 0.2250 | This paper |
Sorted by Accuracy. Highlighted rows are from other papers.
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GAP-EDP | 0.9870
±0.0003 | |
| 2 | NE-ASGCN | 0.9758
±0.0027 | |
| 3 | HSGT | 0.9730
±0.0024 | |
| 21 | GraphSAGE | 0.9653
±0.0011 | |
| 22 | GAT | 0.9650
±0.0011 best reported | best at pub: Hierarchical Transformer for Scalable Graph Learning (IJCAI 2023) best today: A Scalable and Effective Alternative to Graph Transformers (AAAI 2024) |
| 26 | GCN | 0.9648 best reported | best at pub: DropEdge: Towards Deep Graph Convolutional Networks on Node Classification (ICLR 2019) |
| 114 | GraphAny (Wisconsin) | 0.9100
±0.0024 | This paper |
| 147 | MLP | 0.8240
±0.0010 best reported | best at pub: GAP: Differentially Private Graph Neural Networks with Aggregation Perturbation (2022) |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GCN | 0.9302
±0.0011 best reported | best at pub: Augmentation-Free Graph Contrastive Learning with Performance Guarantee (2022) |
| 2 | RSE + RGCN (70b) | 0.8852
±0.0019 | |
| 3 | LEMP+T | 0.8825 | |
| 9 | SAGE | 0.8771 | |
| 31 | GAT | 0.8533 best reported | |
| 232 | GraphAny (Products) | 0.7501
±0.0054 | This paper |
| 237 | MLP | 0.7272
±0.0043 | prev best: Augmentation-Free Graph Contrastive Learning with Performance Guarantee (2022) best today: View Space: Learning Representation across Arbitrary Graphs (ICML 2025) |
OGB
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | Jacobi | 0.8968 | |
| 2 | GPR | 0.8953 | |
| 3 | LEMP4HG | 0.8939 | |
| 4 | SAGE | 0.8933 | |
| 6 | GCN | 0.8868 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 9 | GAT | 0.8829 best reported | best at pub: PaSca: a Graph Neural Architecture Search System under the Scalable Paradigm (WWW 2022) |
| 351 | MLP | 0.6605
±0.0020 best reported | best at pub: SCR: Training Graph Neural Networks with Consistency Regularization (2021) best today: Latent Graph Inference using Product Manifolds (ICLR 2022) |
| 369 | GraphAny | 0.6119
±0.0023 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GIANT-XRT | 0.7612
±0.0016 | |
| 2 | GEGCN | 0.7576
±0.0064 | |
| 3 | AGDN | 0.7522
±0.0007 | |
| 15 | GAT | 0.7365
±0.0011 | prev best: A General Graph Spectral Wavelet Convolution via Chebyshev Order Decomposition (ICML 2024) |
| 23 | GCN | 0.7300
±0.0017 best reported | |
| 25 | GraphSAGE | 0.7277
±0.0016 | |
| 107 | MLP | 0.5765
±0.0012 best reported |
Heterophily Benchmark
Questions
Global leaderboard →Sorted by Accuracy. Highlighted rows are from other papers.
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | MLP | 0.9733 | This paper |
| 2 | AGS-GNN | 0.9727 | |
| 3 | MeanGNN | 0.9716
±0.0006 | |
| 4 | GCN | 0.9715 | prev best: Graph Neural Networks for Graphs with Heterophily: A Survey (2022) |
| 5 | GAT | 0.9711 | prev best: Graph Neural Networks for Graphs with Heterophily: A Survey (2022) |
| 7 | GraphAny | 0.9710 | This paper |
| 33 | SAGE | 0.7644 |