TinyGraph: Joint Feature and Node Condensation for Graph Neural Networks
Abstract
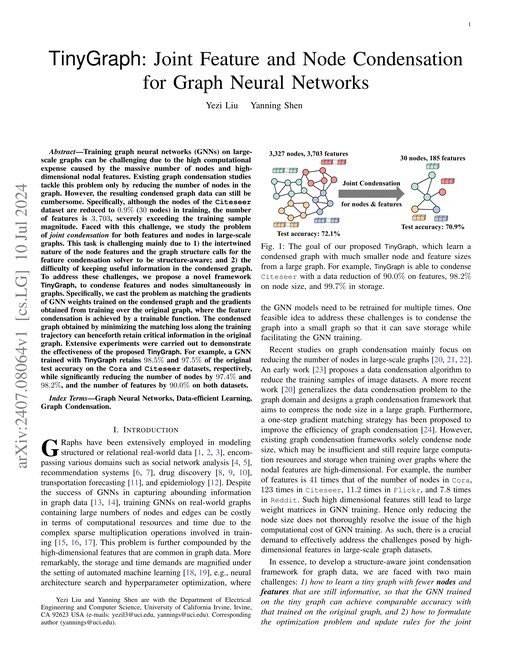
Training graph neural networks (GNNs) on large-scale graphs can be challenging due to the high computational expense caused by the massive number of nodes and high-dimensional nodal features. Existing graph condensation studies tackle this problem only by reducing the number of nodes in the graph. However, the resulting condensed graph data can still be cumbersome. Specifically, although the nodes of the dataset are reduced to $0.9\
Benchmark Results
Tested on 3 datasets Non-standard metric on 1 dataset
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 21 | GCN | 0.9004 | |
| 585 | Original Graph | 0.8130
±0.0040 | This paper |
| 615 | GCond | 0.8090
±0.0320 | prev best: Two Trades are not Baffled: Condensing Graph via Crafting Rational Gradient Matching (2024) Improvement within reported uncertainty; not highlighted. |
| 655 | TinyGraph | 0.8010
±0.0110 | This paper |
| 719 | GCond-LDA | 0.7780
±0.0410 | This paper |
| 720 | GCond-VGAE | 0.7780
±0.0410 | This paper |
| 724 | MLP | 0.7768 | |
| 728 | GCond-PCA | 0.7760
±0.0320 | This paper |
| 768 | GCond-ICA | 0.7540
±0.0350 | This paper |
| 771 | GraphPCA | 0.7530
±0.0200 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | CNA | 0.9575
±0.0058 | |
| 2 | IS-GIB | 0.9390
±0.0187 | |
| 3 | EERM | 0.9112
±0.0145 | |
| 44 | GCN | 0.8033
±0.0088 | |
| 350 | MLP | 0.7289
±0.0010 | |
| 572 | GCond | 0.7080
±0.0450 | prev best: Condensing Graphs via One-Step Gradient Matching (KDD 2022) Improvement within reported uncertainty; not highlighted. |
| 690 | GCond-VGAE | 0.6790
±0.0280 | This paper |
| 715 | GCond-LDA | 0.6720
±0.0120 | This paper |
| 728 | GCond-PCA | 0.6680
±0.0220 | This paper |
| 741 | GCond-ICA | 0.6630
±0.0330 | This paper |
| 802 | GraphPCA | 0.6340
±0.0080 | This paper |
Sorted by Accuracy. Highlighted rows are from other papers.
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GAP-EDP | 0.9870
±0.0003 | |
| 2 | NE-ASGCN | 0.9758
±0.0027 | |
| 3 | HSGT | 0.9730
±0.0024 | |
| 21 | GraphSAGE | 0.9653
±0.0011 | |
| 82 | Original Graph | 0.9390 | This paper |
| 120 | GCond | 0.9030
±0.0310 | prev best: Graph Condensation for Inductive Node Representation Learning (2023) Improvement within reported uncertainty; not highlighted. |
| 129 | TinyGraph | 0.8950
±0.0130 | This paper |
| 131 | GCond-ICA | 0.8920
±0.0370 | This paper |
| 135 | GCond-VGAE | 0.8820
±0.0140 | This paper |
| 136 | GCond-LDA | 0.8740
±0.0170 | This paper |
| 137 | GCond-PCA | 0.8730
±0.0140 | This paper |
| 146 | GraphPCA | 0.8420
±0.0190 | This paper |
| 147 | MLP | 0.8240
±0.0010 |