Scalable Graph Condensation with Evolving Capabilities
Abstract
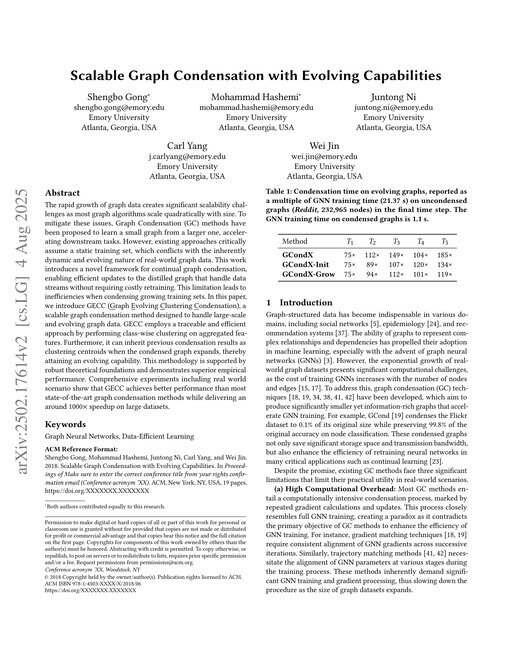
The rapid growth of graph data creates significant scalability challenges as most graph algorithms scale quadratically with size. To mitigate these issues, Graph Condensation (GC) methods have been proposed to learn a small graph from a larger one, accelerating downstream tasks. However, existing approaches critically assume a static training set, which conflicts with the inherently dynamic and evolving nature of real-world graph data. This work introduces a novel framework for continual graph condensation, enabling efficient updates to the distilled graph that handle data streams without requiring costly retraining. This limitation leads to inefficiencies when condensing growing training sets. In this paper, we introduce GECC (raph volving lustering ondensation), a scalable graph condensation method designed to handle large-scale and evolving graph data. GECC employs a traceable and efficient approach by performing class-wise clustering on aggregated features. Furthermore, it can inherit previous condensation results as clustering centroids when the condensed graph expands, thereby attaining an evolving capability. This methodology is supported by robust theoretical foundations and demonstrates superior empirical performance. Comprehensive experiments including real world scenario show that GECC achieves better performance than most state-of-the-art graph condensation methods while delivering an around 1000$ $ speedup on large datasets.
Benchmark Results
Tested on 1 dataset 3 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | CNA | 0.9575
±0.0058 | |
| 2 | IS-GIB | 0.9390
±0.0187 | |
| 3 | EERM | 0.9112
±0.0145 | |
| 44 | GCN | 0.8033
±0.0088 | |
| 244 | SimGC | 0.7380
±0.0250 best reported | best at pub: Simple Graph Condensation (2024) |
| 299 | GECC | 0.7325 | This paper |
| 326 | GEOM | 0.7303 | This paper |
| 350 | MLP | 0.7289
±0.0010 | |
| 593 | Random | 0.7049
±0.0008 best reported | best at pub: NAS-Bench-Graph: Benchmarking Graph Neural Architecture Search (NeurIPS 2022) |
| 632 | GCDM | 0.6980
±0.0020 best reported | best at pub: Simple Graph Condensation (2024) Difference within reported uncertainty; not counted as underperformance. |
| 651 | Herding | 0.6900
±0.0010 best reported | best at pub: Simple Graph Condensation (2024) |
| 675 | GCondX | 0.6838 | This paper |
| 835 | KCenter | 0.5904 | This paper |