LLM as GNN: Graph Vocabulary Learning for Text-Attributed Graph Foundation Models
Abstract
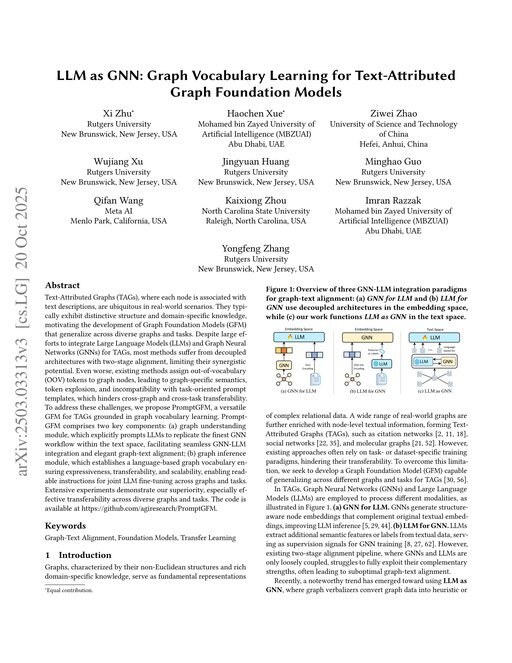
Text-Attributed Graphs (TAGs), where each node is associated with text descriptions, are ubiquitous in real-world scenarios. They typically exhibit distinctive structure and domain-specific knowledge, motivating the development of Graph Foundation Models (GFM) that generalize across diverse graphs and tasks. Despite large efforts to integrate Large Language Models (LLMs) and Graph Neural Networks (GNNs) for TAGs, most methods suffer from decoupled architectures with two-stage alignment, limiting their synergistic potential. Even worse, existing methods assign out-of-vocabulary (OOV) tokens to graph nodes, leading to graph-specific semantics, token explosion, and incompatibility with task-oriented prompt templates, which hinders cross-graph and cross-task transferability. To address these challenges, we propose PromptGFM, a versatile GFM for TAGs grounded in graph vocabulary learning. PromptGFM comprises two key components: (a) graph understanding module, which explicitly prompts LLMs to replicate the finest GNN workflow within the text space, facilitating seamless GNN-LLM integration and elegant graph-text alignment; (b) graph inference module, which establishes a language-based graph vocabulary ensuring expressiveness, transferability, and scalability, enabling readable instructions for joint LLM fine-tuning across graphs and tasks. Extensive experiments demonstrate our superiority, especially effective transferability across diverse graphs and tasks. The code is available at.
Benchmark Results
Tested on 5 datasets 12 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 5 | PromptGFM | 0.9242 | This paper |
| 21 | GCN | 0.9004 | |
| 724 | MLP | 0.7768 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | CNA | 0.9575
±0.0058 | |
| 2 | IS-GIB | 0.9390
±0.0187 | |
| 3 | EERM | 0.9112
±0.0145 | |
| 35 | GAT | 0.8080
±0.0026 best reported | best at pub: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 44 | GCN | 0.8033
±0.0088 | |
| 76 | NodeFormer | 0.7856
±0.0009 best reported | best at pub: NTFormer: A Composite Node Tokenized Graph Transformer for Node Classification (2024) |
| 81 | ENGINE | 0.7846 | This paper |
| 89 | SGFormer | 0.7798
±0.0091 best reported | best at pub: NTFormer: A Composite Node Tokenized Graph Transformer for Node Classification (2024) |
| 103 | RevGNN | 0.7734 | This paper |
| 195 | Llama3 | 0.7468 | This paper |
| 313 | BERT | 0.7317
±0.0175 best reported | best at pub: Efficient Tuning and Inference for Large Language Models on Textual Graphs (IJCAI 2024) Difference within reported uncertainty; not counted as underperformance. |
| 350 | MLP | 0.7289
±0.0010 | |
| 446 | Sentence-BERT | 0.7212 | This paper |
| 503 | OFA | 0.7158 | This paper |
| 659 | LLaGA | 0.6880 | This paper |
| 787 | MLP+LLM_features | 0.6442 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | LGTL | 0.9518
±0.0011 | |
| 2 | MixHop (LO) | 0.9513
±0.0038 | |
| 3 | GraphSAGE (LO) | 0.9511
±0.0036 | |
| 8 | PromptGFM | 0.9465 | This paper |
| 18 | GCN | 0.9296
±0.0015 | |
| 210 | MLP | 0.8690
±0.0074 |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphTARIF | 0.9703
±0.0019 | |
| 2 | GAT | 0.9669
±0.0014 best reported | |
| 3 | GAT+T | 0.9660
±0.0007 | |
| 7 | SAGE | 0.9643
±0.0027 best reported | best at pub: Training MLPs on Graphs without Supervision (2024) |
| 8 | GCN | 0.9632
±0.0008 best reported | |
| 29 | SGFormer | 0.9558
±0.0036 best reported | best at pub: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) |
| 44 | NodeFormer | 0.9527
±0.0022 best reported | best at pub: SignGT: Signed Attention-based Graph Transformer for Graph Representation Learning (2023) best today: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) |
| 56 | GraphSAGE | 0.9508
±0.0026 | |
| 390 | MLP | 0.9128
±0.0063 | |
| 500 | PromptGFM | 0.8661 | This paper |
| 506 | LLaGA | 0.8534 | This paper |
| 513 | OFA | 0.8446 | prev best: Towards Graph Foundation Models: Learning Generalities Across Graphs via Task-Trees (ICML 2024) |
| 521 | ENGINE | 0.8375 | This paper |
| 523 | RevGNN | 0.8324 | This paper |
| 530 | GraphPrompter | 0.8004 | This paper |
| 550 | Llama3 | 0.7442 | This paper |
| 559 | Sentence-BERT | 0.6902 | This paper |
| 560 | BERT | 0.6882 | |
| 562 | MLP+LLM_features | 0.6121 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GCN | 0.9302
±0.0011 best reported | best at pub: Augmentation-Free Graph Contrastive Learning with Performance Guarantee (2022) |
| 2 | RSE + RGCN (70b) | 0.8852
±0.0019 | |
| 3 | LEMP+T | 0.8825 | |
| 9 | SAGE | 0.8771 best reported | best at pub: Efficient Tuning and Inference for Large Language Models on Textual Graphs (IJCAI 2024) |
| 26 | MLP+LLM_features | 0.8597 best reported | |
| 31 | GAT | 0.8533 best reported | best at pub: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) |
| 34 | PromptGFM | 0.8466 | This paper |
| 54 | GIN | 0.8303
±0.0021 | |
| 57 | SGFormer | 0.8271
±0.0056 best reported | best at pub: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) |
| 68 | ENGINE | 0.8156 | This paper |
| 73 | RevGNN | 0.8122 | This paper |
| 74 | NodeFormer | 0.8103
±0.0094 best reported | best at pub: GrokFormer: Graph Fourier Kolmogorov-Arnold Transformers (ICML 2024) |
| 75 | GraphPrompter | 0.8098 | This paper |
| 79 | LLaGA | 0.8074 | This paper |
| 101 | Llama3 | 0.7994 | This paper |
| 156 | OFA | 0.7855
±0.0037 best reported | best today: Towards Effective Federated Graph Foundation Model via Mitigating Knowledge Entanglement (NeurIPS 2025) Difference within reported uncertainty; not counted as underperformance. |
| 165 | BERT | 0.7833
±0.0043 best reported | best at pub: Efficient Tuning and Inference for Large Language Models on Textual Graphs (IJCAI 2024) Difference within reported uncertainty; not counted as underperformance. |
| 186 | Sentence-BERT | 0.7772 | This paper |
| 237 | MLP | 0.7469
±0.0085 |