Simplifying Graph Convolutional Networks with Redundancy-Free Neighbors
Abstract
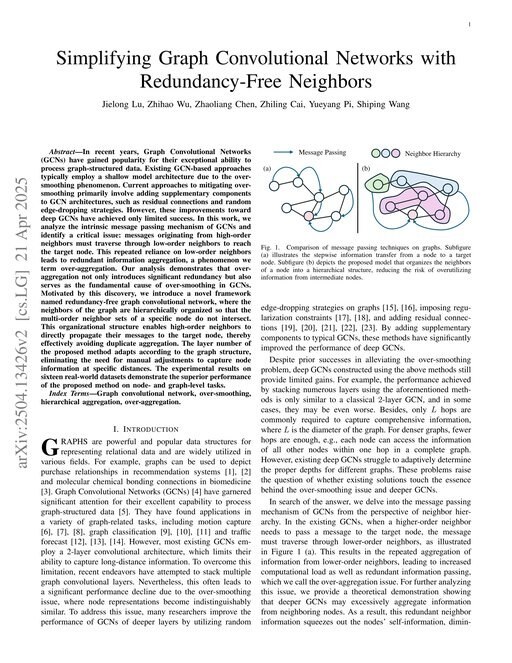
In recent years, Graph Convolutional Networks (GCNs) have gained popularity for their exceptional ability to process graph-structured data. Existing GCN-based approaches typically employ a shallow model architecture due to the over-smoothing phenomenon. Current approaches to mitigating over-smoothing primarily involve adding supplementary components to GCN architectures, such as residual connections and random edge-dropping strategies. However, these improvements toward deep GCNs have achieved only limited success. In this work, we analyze the intrinsic message passing mechanism of GCNs and identify a critical issue: messages originating from high-order neighbors must traverse through low-order neighbors to reach the target node. This repeated reliance on low-order neighbors leads to redundant information aggregation, a phenomenon we term over-aggregation. Our analysis demonstrates that over-aggregation not only introduces significant redundancy but also serves as the fundamental cause of over-smoothing in GCNs. Motivated by this discovery, we introduce a novel framework named redundancy-free graph convolutional network, where the neighbors of the graph are hierarchically organized so that the multi-order neighbor sets of a specific node do not intersect. This organizational structure enables high-order neighbors to directly propagate their messages to the target node, thereby effectively avoiding duplicate aggregation. The layer number of the proposed method adapts according to the graph structure, eliminating the need for manual adjustments to capture node information at specific distances. The experimental results on sixteen real-world datasets demonstrate the superior performance of the proposed method on node- and graph-level tasks. Graph convolutional network, over-smoothing, hierarchical aggregation, over-aggregation.
Benchmark Results
Tested on 6 datasets 8 baseline values reported too low Non-standard metric on 1 dataset
Tables show presented results in global context (best 3 papers + GCN + MLP).
TU Dortmund
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | MSH-GNN | 0.9910
±0.0030 | |
| 2 | ID-GNN+BEC | 0.9830
±0.0360 | |
| 3 | SupCosine | 0.9830
±0.0250 | |
| 39 | GIN | 0.9330
±0.0290 best reported | best at pub: ProtGNN: Towards Self-Explaining Graph Neural Networks (AAAI 2021) Difference within reported uncertainty; not counted as underperformance. |
| 54 | PatchySan | 0.9260
±0.0420 | This paper |
| 63 | GCN | 0.9220
±0.0440 best reported | best at pub: Depth-Adaptive Graph Neural Networks via Learnable Bakry-Émery Curvature (KDD 2025) Difference within reported uncertainty; not counted as underperformance. |
| 92 | RF-GCN | 0.9150
±0.0490 | This paper |
| 158 | GraphSAGE | 0.9040
±0.0780 | |
| 300 | GCKM | 0.8870
±0.0760 | This paper |
| 337 | AWL | 0.8790
±0.0980 | This paper |
| 403 | MLP | 0.8660
±0.0495 best reported | best at pub: Breaking the Limits of Message Passing Graph Neural Networks (ICML 2021) Difference within reported uncertainty; not counted as underperformance. |
| 425 | DGCNN | 0.8583
±0.0116 best reported | best at pub: Deep Learning on Attributed Graphs: A Journey from Graphs to Their Embeddings and Back (2018) best today: Graph Structure Refinement with Energy-based Contrastive Learning (AAAI 2024) |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | MSH-GNN | 0.9410
±0.0330 | |
| 2 | GRDL | 0.8260
±0.0120 | |
| 3 | GMN | 0.8225 | |
| 32 | GIN | 0.7880
±0.0410 best reported | best at pub: Permutation-Invariant graph partitioning: How graph neural networks capture structural interactions? (2023) Difference within reported uncertainty; not counted as underperformance. |
| 37 | RF-GCN | 0.7860
±0.0240 | This paper |
| 67 | SAGE | 0.7726
±0.0228 | |
| 132 | DGCNN | 0.7626 best reported | best at pub: Orthogonal Graph Neural Networks (AAAI 2021) |
| 148 | GCN | 0.7600
±0.0320 | This paper |
| 149 | MLP | 0.7600
±0.0320 | prev best: GNNBenchmark (JMLR 2023) Improvement within reported uncertainty; not highlighted. |
| 156 | PatchySan | 0.7590
±0.0280 | prev best: Memory-Based Graph Networks (ICLR 2020) Improvement within reported uncertainty; not highlighted. |
| 155 | GraphSAGE | 0.7590
±0.0320 | This paper |
| 293 | GCKM | 0.7450
±0.0390 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | WL-MLP | 0.9792 | |
| 2 | MSH-GNN | 0.9640
±0.0070 | |
| 3 | CoCN | 0.8722
±0.0013 | |
| 23 | GCN | 0.8260
±0.0220 best reported | best at pub: Scalable Expressiveness through Preprocessed Graph Perturbations (2024) |
| 30 | GIN | 0.8220
±0.0210 best reported | best at pub: Scalable Expressiveness through Preprocessed Graph Perturbations (2024) Difference within reported uncertainty; not counted as underperformance. |
| 43 | GCKM | 0.8170
±0.0150 | This paper |
| 60 | RF-GCN | 0.8140
±0.0150 | This paper |
| 136 | GraphSAGE | 0.7970
±0.0170 | |
| 151 | MLP | 0.7920
±0.0240 | prev best: Edge Contraction Pooling for Graph Neural Networks (2019) |
| 191 | DGCNN | 0.7759
±0.0224 best reported | best at pub: CogDL: A Comprehensive Library for Graph Deep Learning (WWW 2021) best today: Explainable Graph Representation Learning via Graph Pattern Analysis (IJCAI 2025) |
| 268 | AWL | 0.7390
±0.0190 | This paper |
| 280 | PatchySan | 0.7260
±0.0420 | This paper |
Heterophilic Graphs
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | P^2GNN | 0.9541
±0.0272 | |
| 2 | ACM-GCN | 0.8571 | prev best: From Node Interaction to Hop Interaction: New Effective and Scalable Graph Learning Paradigm (2022) best today: Heterophily-informed Message Passing (TMLR 2025) Improvement within reported uncertainty; not highlighted. |
| 3 | RF-GCN | 0.9429 | This paper |
| 24 | MLP | 0.9136
±0.0070 | |
| 65 | LRGNN | 0.8648 | This paper |
| 123 | LINKX | 0.8346
±0.0061 best reported | best at pub: Differentiable Cluster Graph Neural Network (2024) |
| 138 | SAGE | 0.8269 | |
| 272 | HOG-GCN | 0.7143 | This paper |
| 342 | Geom-GCN | 0.6412 best reported | best at pub: Steering Graph Neural Networks with Pinning Control (2023) |
| 582 | Homophily | 0.0030 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | DiGGR | 0.4535
±0.0353 | |
| 2 | TRIGON | 0.4402
±0.0028 | |
| 3 | DoG | 0.4320
±0.0120 | |
| 16 | ACM-GCN | 0.4198
±0.0089 best reported | best at pub: Diffusion on Graph: Augmentation of Graph Structure for Node Classification (TMLR 2025) best today: $P^2$GNN: Two Prototype Sets to boost GNN Performance (2026) |
| 42 | MLP | 0.4026
±0.0108 | |
| 68 | GraphSAGE | 0.3899
±0.0085 | |
| 87 | Geom-GCN | 0.3810 best reported | best at pub: Beyond Low-frequency Information in Graph Convolutional Networks (AAAI 2021) |
| 117 | LRGNN | 0.3734
±0.0178 best reported | best at pub: Disentangled Generative Graph Representation Learning (2024) |
| 179 | RF-GCN | 0.3618 | This paper |
| 292 | HOG-GCN | 0.3276 | This paper |
| 470 | Homophily | 0.2200 | This paper |
Heterogeneous Graph Benchmarks
ACM
Global leaderboard →Sorted by F1. Highlighted rows are from other papers.
| # | Model | F1 ↑ | Paper |
|---|---|---|---|
| 1 | SPGRL | 0.9398 | |
| 2 | CDC | 0.9360 | |
| 3 | SynC SSL | 0.9274
±0.0004 | |
| 11 | RF-GCN | 0.9153
±0.0070 | This paper |
| 17 | GCN | 0.9049 |