From Model to Data (M2D): Shifting Complexity from GNNs to Graphs for Transparent Graph Learning
Abstract
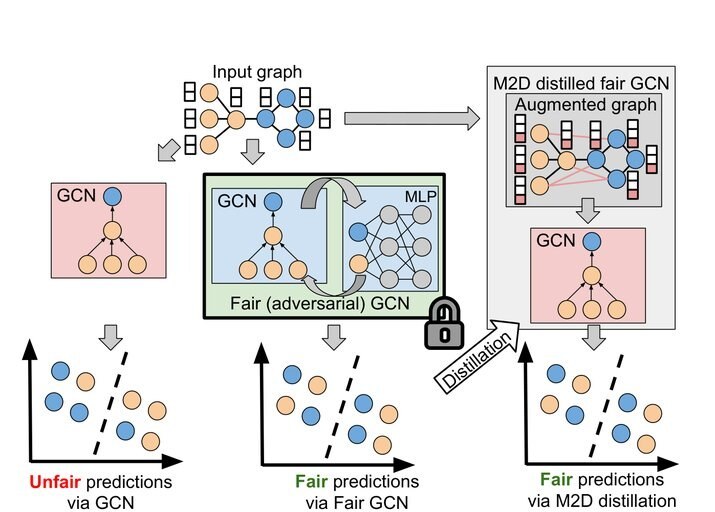
Graph Neural Networks (GNNs) achieve high performance but can be opaque to humans, making it difficult to understand and compare the many proposed architectures. While existing explainability methods attribute individual predictions to nodes, edges, or features, they do not provide architectural transparency or explain the fundamental performance gap between simple and more complex models. To address this limitation, we introduce Model-to-Data (M2D) distillation, a new framework that increases transparency by transferring model complexity into the data space. M2D distills the teacher model into an augmented graph with enriched features and structure, enabling a simple student to match the teacher's performance. By materializing model behavior in the data, our approach allows humans to inspect architectural advantages directly. We show that M2D reveals underlying mechanisms such as fairness objectives and attention-based aggregation in an interpretable way, enhancing GNN transparency while preserving performance.
Benchmark Results
Tested on 5 datasets 8 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
Classic
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphSAGE+CNA | 0.9418
±0.0033 | |
| 2 | GCN+CNA | 0.9366
±0.0048 | |
| 3 | TransformerConv | 0.9350
±0.0058 | |
| 21 | GCN | 0.9004 | |
| 44 | GAT | 0.8897
±0.0014 best reported | |
| 171 | GT | 0.8642 best reported | best at pub: Language is All a Graph Needs (2023) best today: Graph Agent: Explicit Reasoning Agent for Graphs (2023) |
| 468 | M2D | 0.8250
±0.0041 | This paper |
| 573 | GCN (Feat.) | 0.8151
±0.0041 | This paper |
| 724 | MLP | 0.7768 | |
| 865 | MLP (Feat.) | 0.6458
±0.0013 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | CNA | 0.9575
±0.0058 | |
| 2 | IS-GIB | 0.9390
±0.0187 | |
| 3 | EERM | 0.9112
±0.0145 | |
| 35 | GAT | 0.8080
±0.0026 best reported | best at pub: Feature Expansion for Graph Neural Networks (ICML 2023) |
| 44 | GCN | 0.8033
±0.0088 | |
| 335 | GCN (Feat.) | 0.7297
±0.0042 | This paper |
| 350 | MLP | 0.7289
±0.0010 | |
| 639 | MLP (Feat.) | 0.6948
±0.0021 | This paper |
| 768 | GT | 0.6528
±0.0011 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | GraphTARIF | 0.9703
±0.0019 | |
| 2 | GAT | 0.9669
±0.0014 best reported | |
| 3 | GAT+T | 0.9660
±0.0007 | |
| 7 | SAGE | 0.9643
±0.0027 | |
| 90 | GT | 0.9420
±0.0016 | prev best: Towards Deep Attention in Graph Neural Networks: Problems and Remedies (ICML 2023) |
| 390 | MLP | 0.9128
±0.0063 | |
| 397 | GCN (Both) | 0.9117
±0.0039 | This paper |
| 498 | MLP (Feat.) | 0.8694
±0.0014 | This paper |
Heterophilic Graphs
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | P^2GNN | 0.9672
±0.0147 | |
| 2 | DoG | 0.9660
±0.0210 | |
| 3 | GPF-plus | 0.9583
±0.0419 | |
| 34 | MLP | 0.9230
±0.0070 | |
| 53 | GraphSAGE | 0.9000
±0.0365 | |
| 166 | GT | 0.8408
±0.0560 best reported | best at pub: Towards Deep Attention in Graph Neural Networks: Problems and Remedies (ICML 2023) |
| 211 | GAT | 0.8162
±0.0645 best reported | best at pub: Equivariance Everywhere All At Once: A Recipe for Graph Foundation Models (2025) |
| 318 | MLP (Van.) | 0.7527
±0.0020 | This paper |
| 437 | GCN (Feat.) | 0.6559
±0.0022 | This paper |
| # | Model | Accuracy ↑ | Paper |
|---|---|---|---|
| 1 | P^2GNN | 0.9541
±0.0272 | |
| 2 | ACM-GCN | 0.9480
±0.0380 | |
| 3 | RF-GCN | 0.9429 | |
| 24 | MLP | 0.9136
±0.0070 | |
| 138 | SAGE | 0.8269 | |
| 158 | GAT | 0.8190
±0.0540 best reported | best at pub: Restructuring Graphs for Higher Homophily via Adaptive Spectral Clustering (AAAI 2022) |
| 179 | GT | 0.8000
±0.0490 best reported | best at pub: Towards Deep Attention in Graph Neural Networks: Problems and Remedies (ICML 2023) |
| 317 | MLP (Van.) | 0.6634
±0.0018 | This paper |
| 388 | M2D | 0.5914
±0.0023 | This paper |
| 417 | GCN (Feat.) | 0.5714
±0.0023 | This paper |