From Message-Passing to Linearized Graph Sequence Models
Abstract
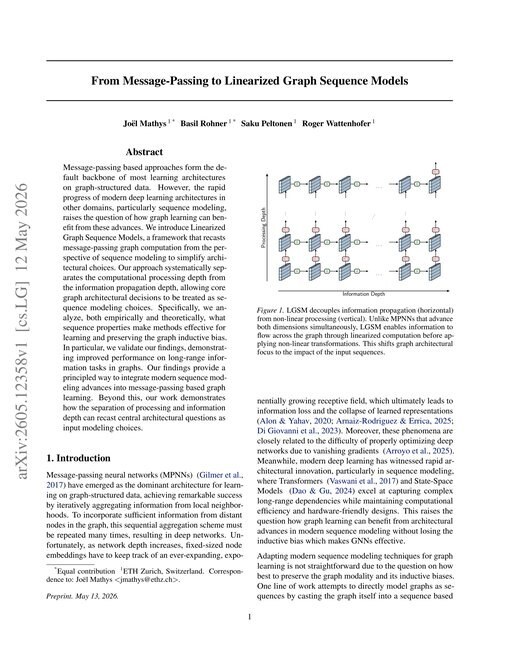
Message-passing based approaches form the default backbone of most learning architectures on graph-structured data. However, the rapid progress of modern deep learning architectures in other domains, particularly sequence modeling, raises the question of how graph learning can benefit from these advances. We introduce Linearized Graph Sequence Models, a framework that recasts message-passing graph computation from the perspective of sequence modeling to simplify architectural choices. Our approach systematically separates the computational processing depth from the information propagation depth, allowing core graph architectural decisions to be treated as sequence modeling choices. Specifically, we analyze, both empirically and theoretically, what sequence properties make methods effective for learning and preserving the graph inductive bias. In particular, we validate our findings, demonstrating improved performance on long-range information tasks in graphs. Our findings provide a principled way to integrate modern sequence modeling advances into message-passing based graph learning. Beyond this, our work demonstrates how the separation of processing and information depth can recast central architectural questions as input modeling choices.
Benchmark Results
Tested on 3 datasets 3 baseline values reported too low
Tables show presented results in global context (best 3 papers + GCN + MLP).
LRGB
| # | Model | MAE ↓ | Paper |
|---|---|---|---|
| 1 | GCN | 0.2421
±0.0016 | This paper |
| 2 | IPR-MPNN | 0.2422
±0.0007 | |
| 3 | TANGO-GPS | 0.2422
±0.0014 | |
| 5 | GIN | 0.2429
±0.0019 | This paper |
| 7 | GatedGCN | 0.2431
±0.0020 | This paper |
| 30 | GRAMA_GatedGCN | 0.2459
±0.0020 | This paper |
| 37 | NeuralWalker | 0.2463
±0.0005 | prev best: Chimera: State Space Models Beyond Sequences (TMLR 2025) Improvement within reported uncertainty; not highlighted. |
| 45 | LGSM | 0.2470
±0.0019 | This paper |
| 49 | GINE | 0.2473
±0.0017 | This paper |
| 50 | GMN | 0.2473
±0.0025 | This paper |
| 62 | Graph-Mamba | 0.2478
±0.0016 | This paper |
| 68 | SWAN | 0.2485
±0.0009 | This paper |
| 88 | GraphGPS+LapPE | 0.2500
±0.0005 | This paper |
| 104 | DRew-GCN+LapPE | 0.2517
±0.0011 | prev best: TANGO: Graph Neural Dynamics via Learned Energy and Tangential Flows (2025) Improvement within reported uncertainty; not highlighted. |
| 113 | Transformer+LapPE | 0.2529
±0.0016 | This paper |
| 116 | DRew-GCN | 0.2536 best reported | best at pub: Towards Dynamic Message Passing on Graphs (NeurIPS 2024) |
| 120 | DRew-GatedGCN+LapPE | 0.2539
±0.0007 | This paper |
| 146 | DRew-GIN+LapPE | 0.2606
±0.0014 | This paper |
| 149 | MixHop-GCN+LapPE | 0.2614
±0.0023 | This paper |
| 150 | DIGL+MPNN+LapPE | 0.2616
±0.0018 | This paper |
| 155 | SAN+LapPE | 0.2680
±0.0040 best reported | best at pub: Learning Efficient Positional Encodings with Graph Neural Networks (ICLR 2025) Difference within reported uncertainty; not counted as underperformance. |
| 158 | DRew-GatedGCN | 0.2699
±0.0018 | This paper |
| 165 | GraphCON | 0.2778
±0.0018 | This paper |
| 166 | DRew-GIN | 0.2799
±0.0016 | This paper |
| 170 | A-DGN | 0.2874
±0.0021 | This paper |
| 171 | MixHop-GCN | 0.2921
±0.0023 | This paper |
| 174 | DIGL+MPNN | 0.3173
±0.0007 | This paper |
| 182 | GRAND | 0.3418
±0.0015 | This paper |
| 201 | MLP | 0.4351
±0.0008 |
| # | Model | AP ↑ | Paper |
|---|---|---|---|
| 1 | S^2GCN | 0.7311
±0.0066 | |
| 2 | S4G | 0.7293
±0.0004 | |
| 3 | BuNN | 0.7276
±0.0065 | |
| 4 | GCN | 0.7261
±0.0011 | |
| 11 | DRew-GCN | 0.7150
±0.0044 best reported | best at pub: Spatio-Spectral Graph Neural Networks (NeurIPS 2024) |
| 12 | DRew-GCN+LapPE | 0.7150
±0.0044 | This paper |
| 17 | DRew-GIN+LapPE | 0.7126
±0.0045 | This paper |
| 20 | NeuralWalker | 0.7096
±0.0078 | This paper |
| 24 | GMN | 0.7071
±0.0083 | This paper |
| 26 | GIN | 0.7059
±0.0089 | prev best: Position: Don't be Afraid of Over-Smoothing And Over-Squashing (2026) |
| 27 | GRAMA_GatedGCN | 0.7049
±0.0051 | This paper |
| 34 | GatedGCN | 0.7006
±0.0033 | prev best: Where Did the Gap Go? Reassessing the Long-Range Graph Benchmark (TMLR 2023) |
| 38 | DRew-GatedGCN+LapPE | 0.6977
±0.0026 | This paper |
| 46 | DRew-GIN | 0.6940
±0.0074 | This paper |
| 51 | MixHop-GCN+LapPE | 0.6843
±0.0049 | This paper |
| 52 | DIGL+MPNN+LapPE | 0.6830
±0.0026 | This paper |
| 60 | SWAN | 0.6751
±0.0039 | This paper |
| 62 | Graph-Mamba | 0.6739
±0.0087 | This paper |
| 63 | DRew-GatedGCN | 0.6733
±0.0094 | This paper |
| 72 | LGSM | 0.6685
±0.0136 | This paper |
| 75 | GRAND | 0.6630
±0.0160 best reported | |
| 78 | GINE | 0.6621
±0.0067 | This paper |
| 81 | MixHop-GCN | 0.6592
±0.0036 | This paper |
| 92 | GraphGPS+LapPE | 0.6535
±0.0041 | This paper |
| 108 | DIGL+MPNN | 0.6469
±0.0019 | This paper |
| 116 | SAN+LapPE | 0.6384
±0.0121 | This paper |
| 118 | Transformer+LapPE | 0.6326
±0.0126 | This paper |
| 137 | GraphCON | 0.6022
±0.0068 | This paper |
| 139 | A-DGN | 0.5975
±0.0044 | This paper |
| 181 | MLP | 0.4060
±0.0021 |
LRIM Graph Benchmark
| # | Model | log-MSE ↓ | Paper |
|---|---|---|---|
| 1 | GPS-RWSE | -4.3450
±0.0650 | This paper |
| 2 | GPS-Base | -4.3400
±0.1010 | This paper |
| 3 | GPS-LapPE | -4.3340
±0.0650 best reported | best today: Graph Hierarchical Recurrence for Long-Range Generalization (2026) Difference within reported uncertainty; not counted as underperformance. |
| 4 | LGSM | -4.2840
±0.1330 | This paper |
| 6 | GatedGCN | -3.9190
±0.2230 | This paper |
| 7 | GatedGCN-VN_G | -3.7560
±0.0630 | This paper |
| 8 | GIN | -2.4060
±0.1480 | This paper |